Simon Willison’s Weblog
Introducing Our Smallest, Most Efficient Model: Muse Ember . Meta AI just launched their entry in the Claude Haiku/GPT Luna category: Muse Ember, which they describe as:
[...] our smallest and most efficient model designed for complex reasoning execution and the work agents repeat all day: tool calls, coding subtasks, routing, extraction, and long document parsing.
For shorter prompts it's priced the same as GPT-6 Luna and Claude Haiku 5.5 - both are $0.10/million input tokens and $0.50/million output. Today's other big model release, Claude Fable 5.2, is 80x that price at $8/$40.
The pricing is a little less straightforward as prompts get longer, though. Luna, Ember, and Haiku all support up to a million input tokens, but they also all have a threshold after which the price goes up. Taking that threshold into account Ember is priced between the two others:
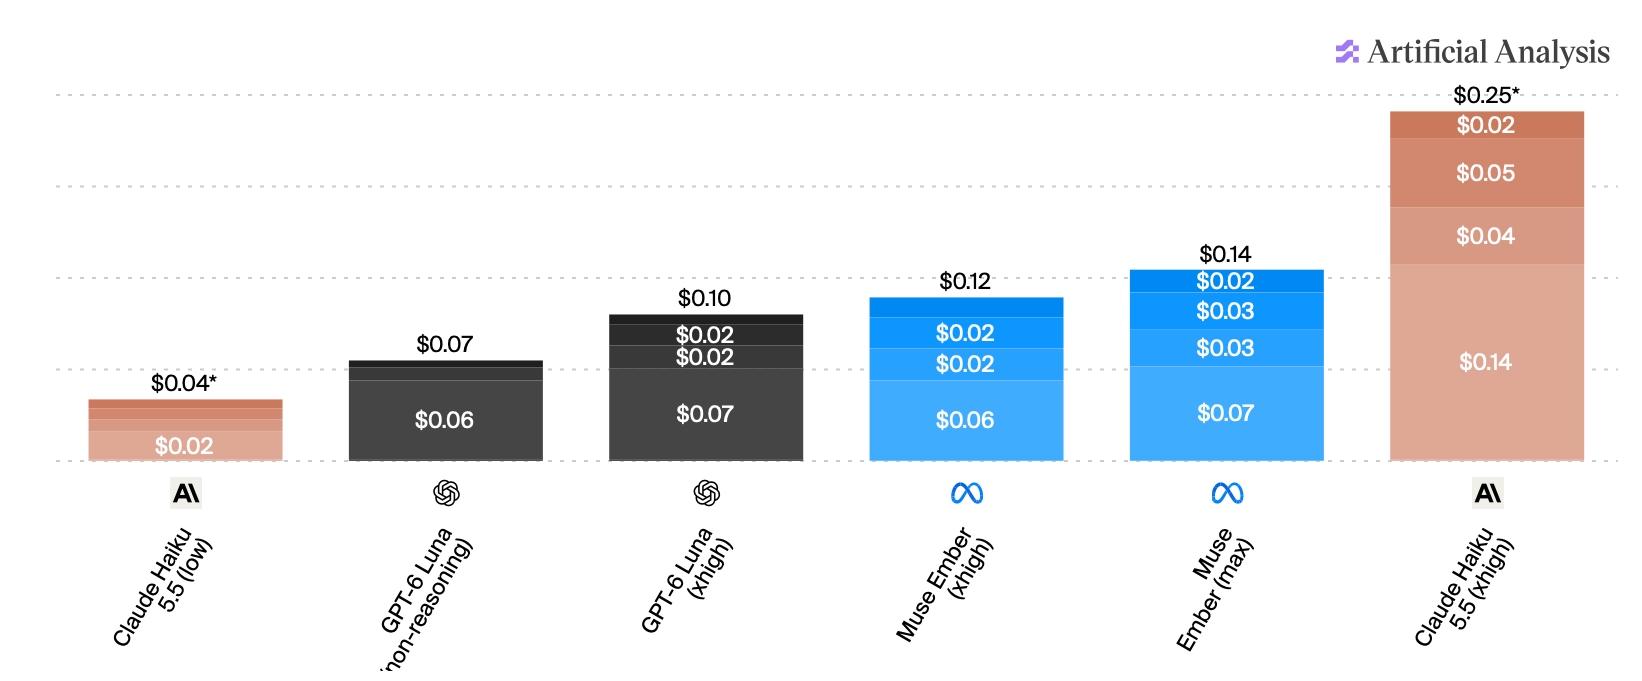
But comparing price-per-token doesn't really make sense these days, when reasoning tokens mean that different models might use dramatically different numbers of tokens to solve the same problem.
For that, one measure that's useful is the Artificial Analysis.
And even more useful than that is their Intelligence Index vs. Cost per Task chart, which shows the following for those three models:
The Muse Ember models sit right on that Pareto line - the line at which you can only improve one dimension by giving up another. Meta call this out in their announcement:
It also sits on the efficiency frontier of the full Artificial Analysis leaderboard: no model scores higher for less per task.
(That grey dot on the Pareto line in the middle of the green area is GPT-6.1 Terra (low) - clearly I should be paying more attention to the Terra family!)
Muse Ember has six reasoning levels - minimal, low, medium, high, xhigh, and max - so I rendered six pelicans riding bicycles . The "high" reasoning level failed to return a full SVG, and the other SVGs were surprising in that the reasoning level didn't cleanly map to the visual quality of the response.
Here's the "max" one, but the others are worth a look too:
The Ember pelicans are comparable in quality to those I got from Muse Wonder , which is 40x the price of Muse Ember.
Recent articles
Locating the source of a mysterious beep with Claude - 9th November 2026
Hide your slop PR descriptions behind <details><summary> - 9th November 2026
Qwen 3.8 27B on my laptop can interpret model weights, too - 3rd November 2026
The U.S. Census Bureau and “Super Intelligence” - 2nd November 2026
This is a link post by Simon Willison, posted on 10th November 2026 .
Monthly briefing
Sponsor me for $10/month and get a curated email digest of the month's most important LLM developments.