Latest commit
History
Folders and files
Repository files navigation
MuscleMemory
Open-source procedural memory for AI agents. It learns from what worked and what failed. Local by default · Apache-2.0 · by TheWariend
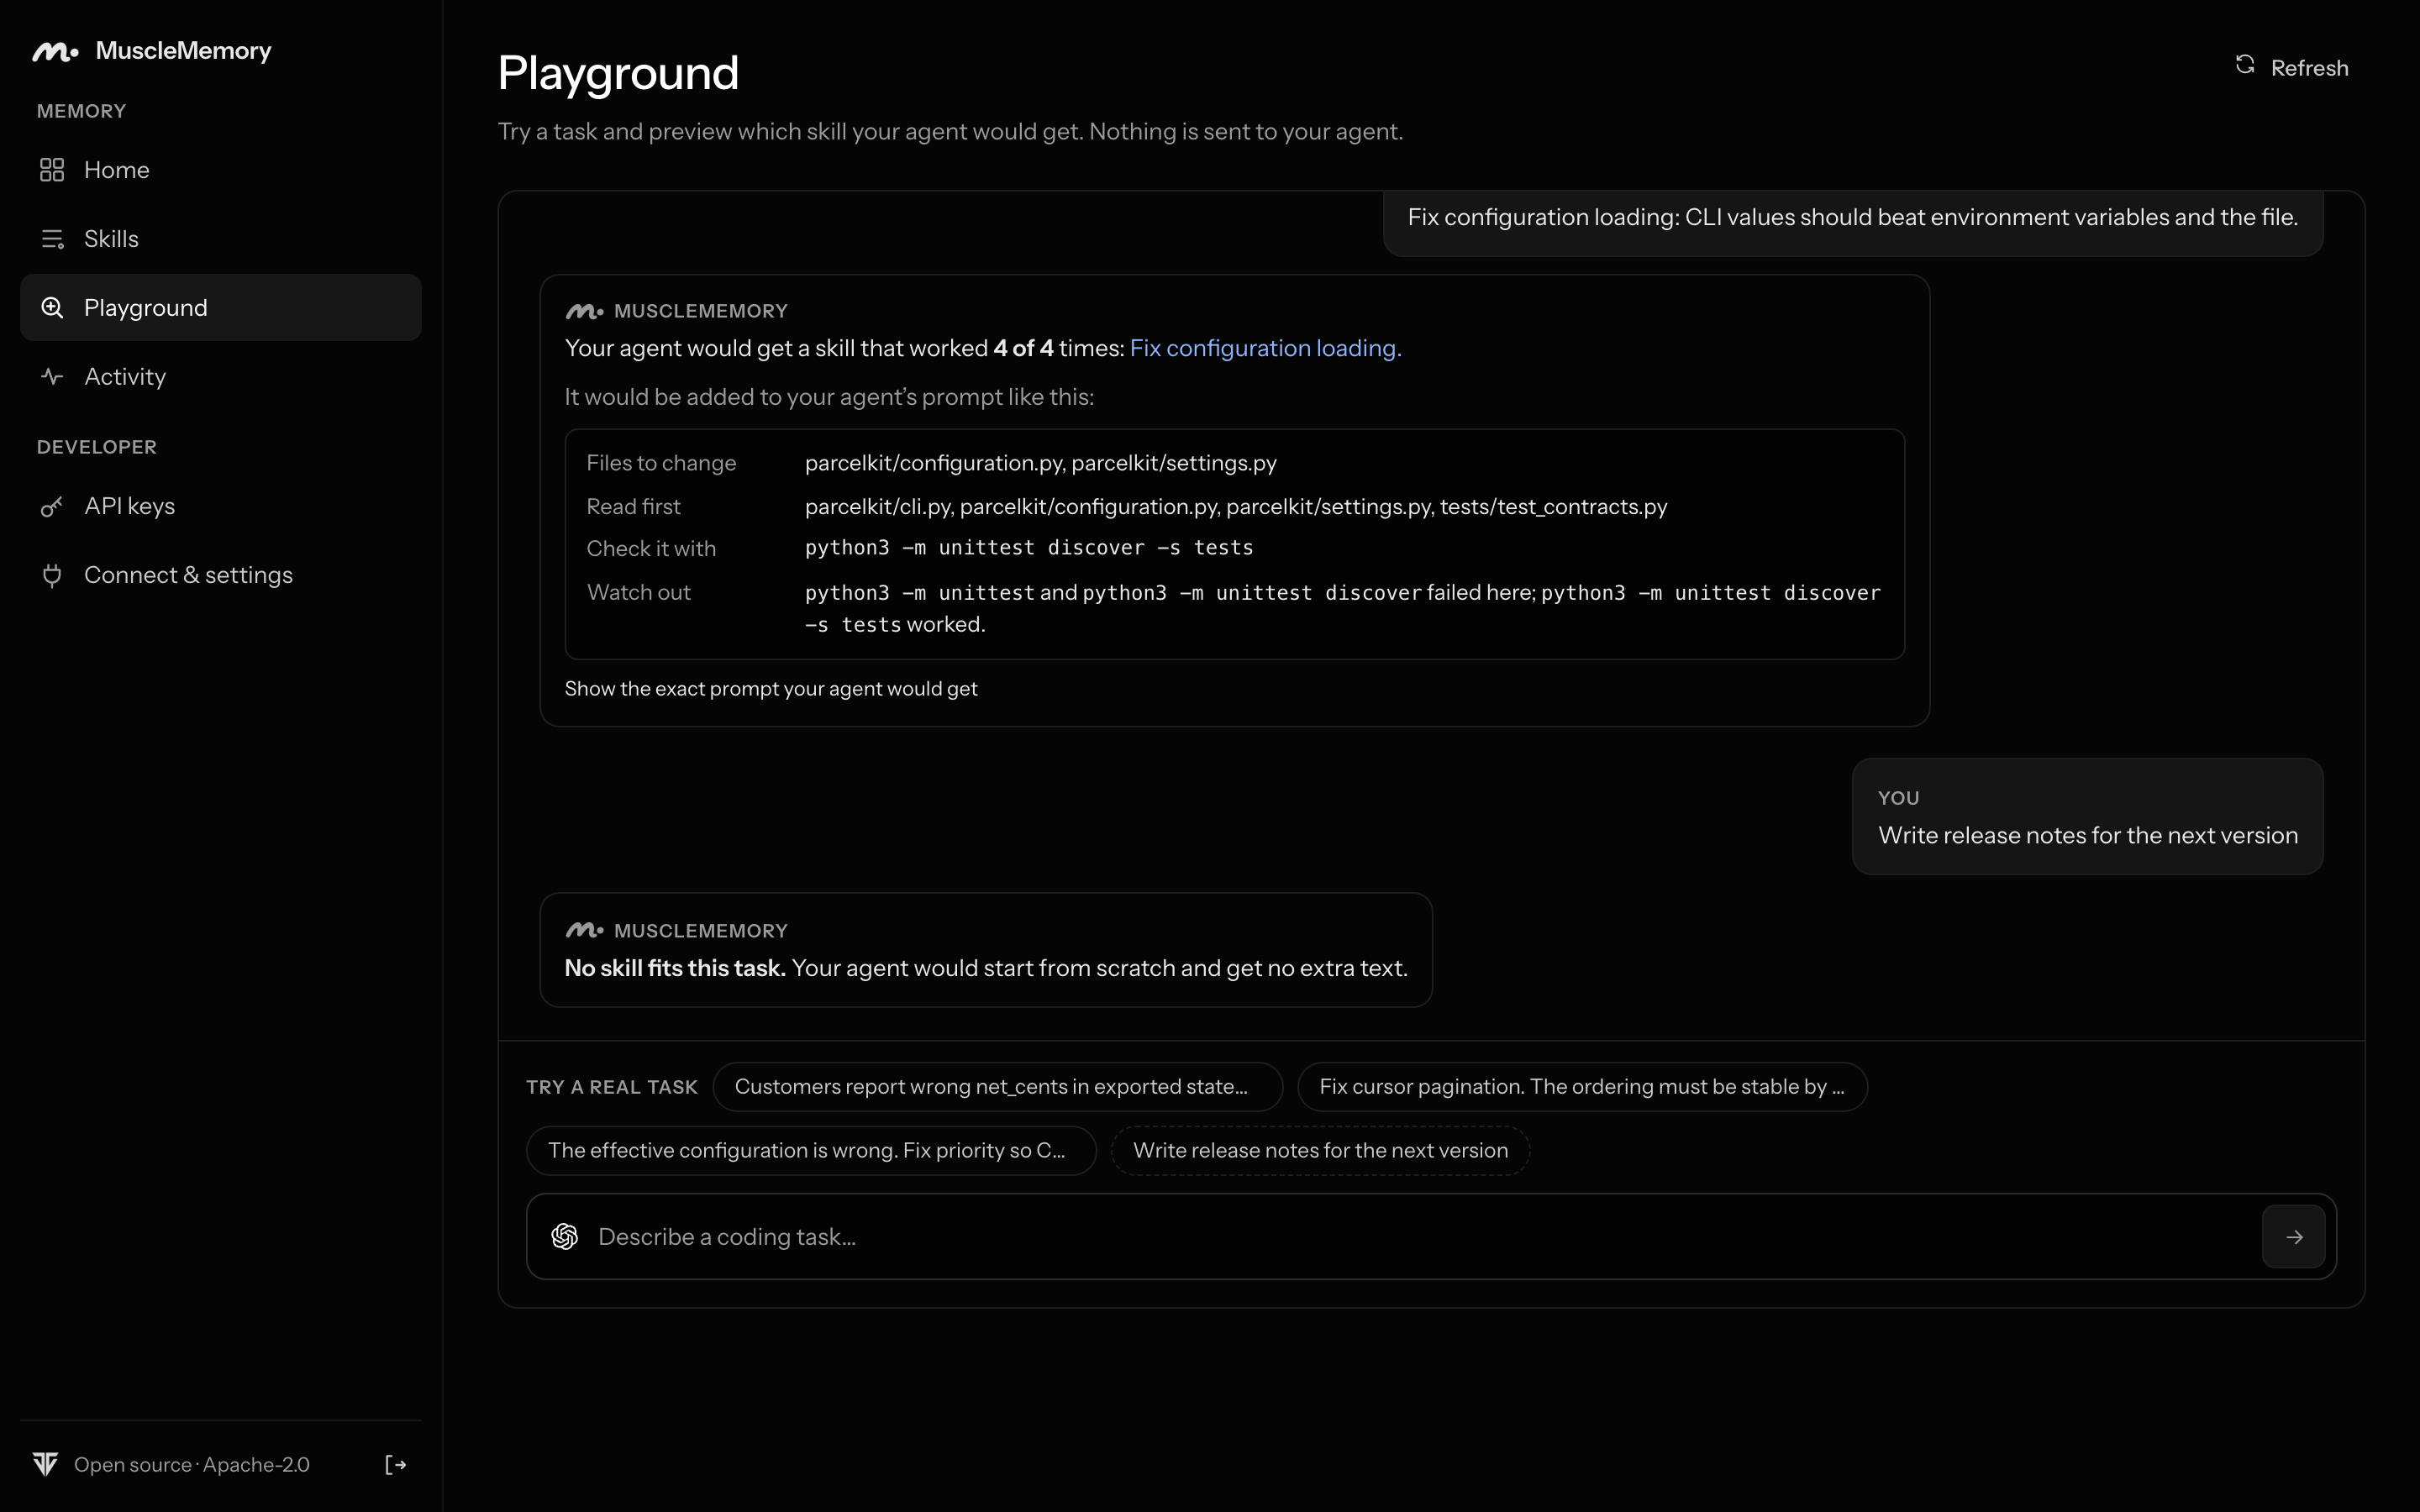
Coding agents relearn the same things every session: which files to open, how the tests run, what broke last time. MuscleMemory watches your agent work. When a task really succeeds (the tests pass after the last change), it learns how the task was done. The next time a similar task comes up, it hands the agent a short note: the files to change, the test that proves it worked, and what to avoid.
In a benchmark with real Codex sessions, it cut input tokens by 25.5%, tool calls by 30.4% and time by 28.2% , with every task still passing. In an early run with Claude Code and Sonnet 5.5, using skills that Codex had learned, it cut input tokens by 43.5% and tool calls by 30% . On real Django issues from SWE-bench, with a skill learned from other issues in the same area, Codex solved as many as without memory with about half the tokens (a small run; details ). Check them yourself: python benchmarks/reproduce.py check . Codex method and data · Claude Code run · Whitepaper .
Quick start
pipx install thewariend-musclememory # or, from a clone: pip install -e . musclememory init # sets up ~/.musclememory and the small search model musclememory start # runs in the background on http://127.0.0.1:8080 cd your-project && musclememory connect codex # or claude, cursor, cleanslate musclememory dashboard # opens the dashboard, already signed in
Then use your agent as usual. There are no keys or config files to copy.
Or let your agent set it up: paste this into Claude Code, Codex or Cursor.
Read https://thewariend.com/musclememory/llms.txt and set up MuscleMemory for this project.
How it works
flowchart LR A["Your agent works on a task"] --> B{"Tests pass after the last change?"} B -- no --> C["Nothing is learned"] B -- yes --> D["Learn a skill or count a check"] D --> E["Two separate passing checks"] E --> F["You tap Keep"] F --> H["Hook checks current files"] H -->|"match or partial match"| G["Short note; warning on partial match"] H -->|"mismatch"| I["No note; skip recorded locally"] G --> A
Verified, twice. Two later sessions must match the skill's actions and pass its own stored test command after the last code change. Pipes, redirects and shell wrappers are normalized; parameterized commands keep shape matching. Automatic checks use the final passing test, so an unrelated test cannot count. The training session doesn't count. Only real test runs count ( pytest , python -m unittest , go test , cargo test , npm test , make test and similar); commands that only mention tests, like cargo build or ruff check , don't.
One failure pulls it. If an agent was given a skill, changed code, and the skill's own test then failed as the last test run, the hooks report a failed check and the skill stops reaching agents. A session that just stops, or where a different test failed, doesn't count against it.
Learns from failures. Failed attempts become plain "watch out" and "if it goes wrong" notes, so the agent avoids the same dead ends.
You stay in charge. Every skill waits for your OK before any agent sees it, however it was learned (hooks, SDK, MCP or the API), and so does every new version. Only the dashboard can approve; an agent's own key can't. Skills you delete or retire stay removed: the same skill isn't learned again. Agents still read the current files and ask for approval as usual. MuscleMemory never replays actions.
Checks current files. Native hooks require the files a skill found in place to still exist (files it created may not exist yet) and at least one stored before or after edit to match. If none match, they stay quiet; partial matches include a warning that cannot be trimmed. Reads are bounded and reject symlinks. File-check skips are recorded locally. Server and MCP recall have no file access. Exact rules .
Quiet when it should be. If nothing fits, nothing is added, and the agent pays no extra tokens.
Shared between agents. A skill learned with Codex is handed to Claude Code or Cursor too: changing a file counts the same whichever tool did it. Proven skills can also be exported to Codex or Claude Code as SKILL.md .
Local and open. SQLite and a small on-device model by default: no account and no outside calls. Use PostgreSQL with pgvector for teams.
Works with
Projects share skills within the same workspace ( namespace , default "default" ), rather than getting a separate workspace per repository. Cross-repository recall is untested. Give a project its own namespace .
Dashboard
Docs
Whitepaper : the design, trust rules, retrieval and evaluation in one paper
Install and run : local setup, Docker and PostgreSQL, configuration
How it works : the learning loop, retrieval, storage and security
Integrations : each agent, MCP and the SDKs
Benchmarks : results, method and limits
API contracts : MCP tools and REST
Roadmap : what's next and known limits
Status
MuscleMemory has Python and TypeScript tests, with optional PostgreSQL and live Codex checks. It's early. The benchmarks cover repeat tasks on three controlled codebases, not every kind of work, and the Claude Code run is small. The hooks and CleanSlate learn on their own; with the SDKs your code reports when a task succeeded. See the roadmap .
Issues and pull requests are welcome. Please report security issues privately, as described in SECURITY.md .
License
About
Open-source procedural memory for AI agents. Learns from what worked and what failed.