Top Chinese Frontier AI Models Carry the Fingerprint of Export-Controlled NVIDIA Blackwell GPUs
Executive Summary
Our forensic analysis of publicly released AI models finds evidence that DeepSeek, Moonshot AI, MiniMax and Ant Group have gained access to NVIDIA’s Blackwell GPUs, despite restrictions on exporting these chips to China, and are using that hardware to create their AI models. Six models released by these companies since April 2026 contain numerical patterns matching Blackwell hardware, whereas earlier models from the same companies match NVIDIA’s older Hopper generation. The findings suggest that several leading Chinese AI developers have begun using Blackwell to train their newest models. U.S. officials and press reports had already alleged that DeepSeek and Moonshot AI were using Blackwell chips, without publishing technical evidence.
The evidence comes entirely from the models’ own published weights, rather than from leaks or insider accounts. We recover traces of the models’ initial values, and then search for the hardware configurations and initial configurations that reproduce them; for DeepSeek-V4-Flash and Kimi K3, we also confirmed the match on physical Blackwell chips. The fingerprint identifies how the weights were created and supports, without proving, the inference that Blackwell also performed the training. Specially configured AMD hardware, which is also restricted from export to China, is the only alternative we have identified; we have excluded it for DeepSeek-V4-Flash, and consider it very unlikely for the other five models. Notably, our findings provide technical evidence of access to advanced computing hardware, but do not establish where the chips were located, how access was obtained, or whether export controls were violated.
Table 1. Hardware fingerprints in successive models from DeepSeek, Moonshot AI, MiniMax and Ant Group Link ↗
• Requires a U.S. license for export to China; none have been reported.
A Hopper fingerprint cannot distinguish an H800 from an H100 SXM or H200; the H800 identifications above are lab disclosures, not findings of this method.
Main Findings
Six models from four Chinese labs read as Blackwell-trained. DeepSeek-V4-Flash and MiniMax-M3 match NVIDIA’s Blackwell-class B200 or B300 chips, which have 148 processor cores (called streaming multiprocessors , or SMs). DeepSeek-V4-Pro, Kimi K3, Kimi K3.1-Pro and Ling-3.1-flash match the GB200 or GB300 chips, also Blackwell-class, which have 152 processor cores. Kimi K3.1-Pro starts from the same seed as K3, and may be a checkpoint of K3 with further post-training.
Chinese labs started training on Blackwell relatively recently. DeepSeek’s models read as Hopper-trained through DeepSeek-V3 (released in December 2024), and as Blackwell from DeepSeek V4 (released in April 2026). Moonshot’s models read as Hopper through Kimi K2.5 (January 2026) and as Blackwell from K3 (July 2026). One Moonshot model sits in between: Kimi K2.7-Code, posted six weeks before K3, is built on the Hopper-era weights but contains a small part that matches the B200 or B300. MiniMax’s models read as Hopper through M2.7 (April 2026) and as Blackwell from M3 (June 2026). Ant Group’s Ling-3.0-flash (August 2026) reads as Hopper, while its Ling-3.1-flash (October 2026) reads as Blackwell. The Hopper readings do not identify a specific chip: H800s, H100 SXMs and H200s share the same fingerprint.
Not every Chinese AI lab has switched to Blackwell. The newest models we could read from Alibaba (Qwen), Zhipu (GLM), Tencent, Xiaomi and StepFun all read as Hopper-trained. Meituan says its LongCat-2.0 was trained entirely on “AI ASIC superpods,” and we found no NVIDIA fingerprint in the model weights it’s released.
The method gets known answers right. For 24 specific models, the developer has publicly said what hardware was used. In every case, our method agrees with the public announcement. NVIDIA’s own Nemotron-3 Ultra, whose technical report names the GB200 for one phase of its training, reads as 152 SMs, the same as Kimi K3.
The matches are far stronger than chance would explain. Even unrelated numbers can appear to match when enough combinations are tried. Across the roughly 6 trillion seed-and-layout combinations in our search, the strongest chance match would be expected to reach about 8 sigma—a measure of how far a result stands above ordinary random variation. The strongest evidence for each of the six models ranges from 49 to 1,385 sigma. Even the weakest individual test we report reaches 20 sigma.
The training runs were data-center scale. From each model’s size and the amount of data it was trained on, we estimate that the two largest runs, Kimi K3 and DeepSeek-V4-Pro, each needed thousands of Blackwell GPUs for two to three months, assuming each model was trained on the hardware that initialized it. Our best estimates are about 4,500 and 3,000, the equivalent of about 11,500 and 7,500 H100s, the previous-generation NVIDIA chip in which AI training clusters are commonly sized, and about 12,000 Blackwell GPUs across the five runs (Table 2). At roughly $70,000 per GPU—the cost implied by a Wall Street Journal report that about 36,000 Blackwell chips being installed in Malaysia for ByteDance’s use would cost more than $2.5 billion—the largest of these clusters would cost roughly $200 million to $300 million, and the five together more than half a billion dollars. These figures cover only the final training runs; the labs’ total spending on export-controlled GPUs is likely in the billions of dollars.
Table 2. Rough scale of each training run Link ↗
Each estimate is a run’s training compute divided by what one Blackwell GPU delivers over the run, rounded to the nearest 500. Training compute is about six operations per active parameter for every training token, plus attention. We assume the GPUs ran at about 20% of their peak speed, in line with other disclosed Blackwell training runs (25% for DeepSeek, which has reported 39% for its previous model), and for the run lengths shown, which we estimate from release timelines. H100 equivalents convert at NVIDIA’s published peak speeds: a B200 or B300 equals about 2.3 H100s, and a GB200 or GB300 about 2.5.
We are not confident in these estimates. They rest on assumptions that the weights cannot confirm: how efficiently each lab used its GPUs (often called MFU), which no lab has published for these runs; how many tokens each model was trained on (DeepSeek’s counts are its own, and we take them on trust; the others are our estimates, made from the weights by a method we have not yet published); how long each run lasted, which no lab has stated; and that training stayed on the hardware that created the weights. Run length matters most, because halving it doubles the GPU count. Two disclosed runs on the same hardware show the spread: Mistral says it trained Mistral Large 4, which has the same number of active parameters as DeepSeek-V4-Pro, on 3,800 Grace Blackwell GPUs, while Microsoft says it trained MAI-Base-2, a model of similar size trained on more data, on 16,000 in 38 days. At that pace the two largest runs here would have needed about 8,000 to 9,000 Blackwell GPUs. The figures cover only the final training run of each model, not experiments, earlier runs or serving.
Revised November 12, 2026. The first version of this report gave 2,000 to 3,000 Blackwell GPUs for the largest runs and $150 million to $200 million for the largest cluster. Those figures assumed the GPUs ran as efficiently as NVIDIA’s own benchmarks, and training runs disclosed on Blackwell have been less efficient. The estimates above replace them. We have also added H100 equivalents and estimated run lengths.
Our investigation
A model’s weights , also called parameters , are the billions of adjustable numbers that determine how it processes information and produces answers. Training repeatedly adjusts these numbers; but before training can begin, they need initial values. In the software examined here, those values come from a pseudorandom number generation (PRNG) algorithm called Philox: Philox produces seemingly random numbers in a deterministic way. The starting input for Philox is a number called the “seed.” Given the same seed and settings, Philox produces the same numbers every time. This lets engineers repeat an experiment from the same starting point.
To fill billions of weights quickly, PyTorch, the software framework used in the development of most major AI models, divides the work that Philox does among many parallel workers on the GPU, called threads . (It does this through cuRAND, NVIDIA’s library for random number generation.) Each thread generates its own sequence of numbers from the seed and fills a particular set of positions. The number of threads then determines how those positions are shared out. On the NVIDIA chips examined here, a sufficiently large initialization uses the maximum of 2,048 threads for each processing unit, called a streaming multiprocessor (SM). A chip with more SMs therefore assigns the same job to more workers, changing where their numbers go.
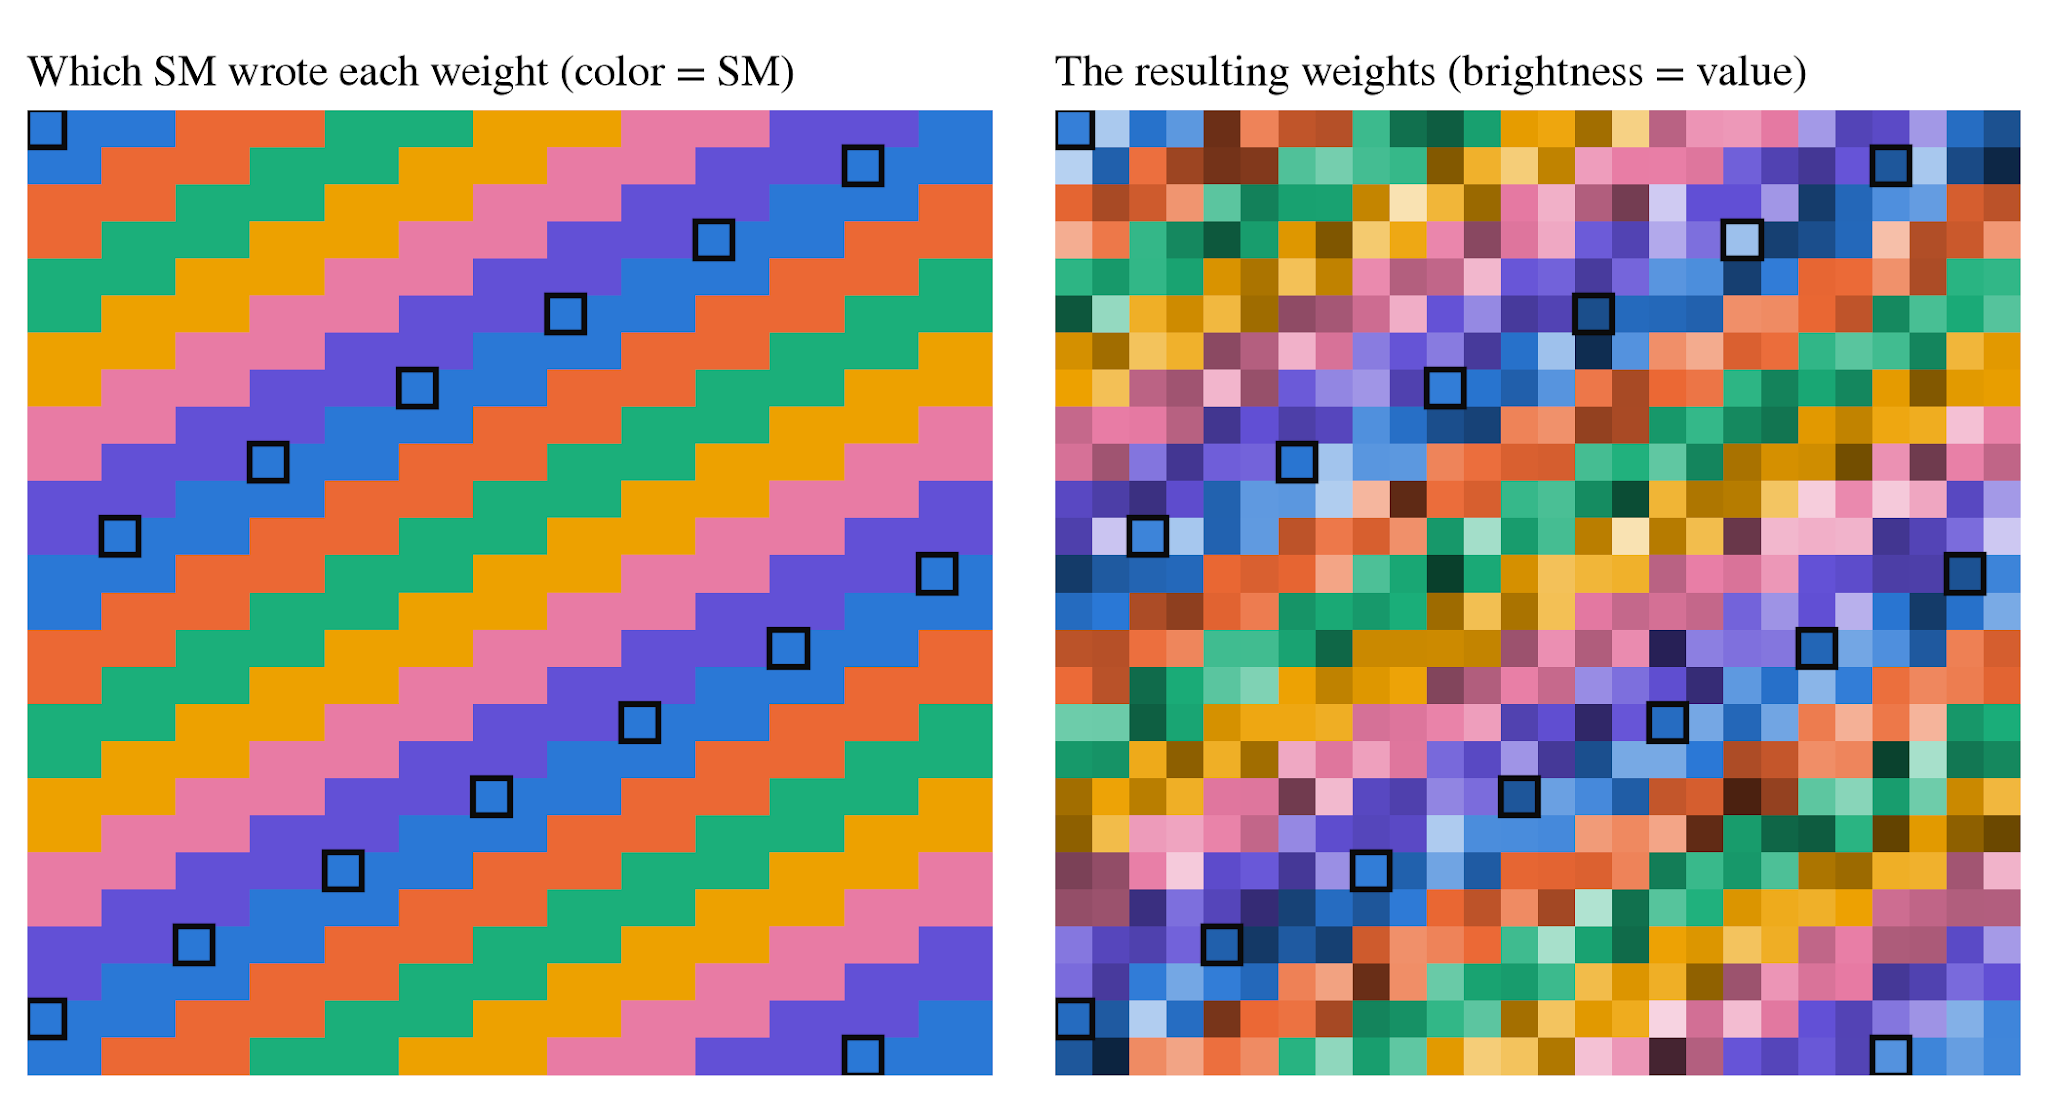
Figure 1 illustrates how this works on a simplified GPU with six SMs and eight threads per SM, giving 48 threads in total. Imagine the weights as a long row of empty boxes, wrapped into a grid to fit on the page. The first thread fills the first box, the second fills the second box, and so on through all 48 threads. The first thread’s next number then goes into box 49, its next into box 97, and so forth. The black outlines follow this one thread through the grid: the first thread fills every 48th position. The colors identify which processing unit supplies each set of values, while the brightness in the right-hand panel represents the value itself.
Now keep the seed fixed, but use a GPU with five SMs instead of six. In our simplified example, that means 40 threads rather than 48. The first thread generates exactly the same sequence, but now puts its numbers in boxes 1, 41, 81, and so on, rather than boxes 1, 49, 97. Figure 2 follows these numbers as their positions change. Across the grid, only 6 percent of the values match the original arrangement. The seed is right, but the worker count is wrong. That is what makes the arrangement of model weights a clue to the chip used to create it.
Reproducing the weights therefore requires two things to be right at once. The seed must generate the right numbers, and the thread count must put them in the right places. A correct seed with the wrong thread count mostly gives the right numbers in the wrong positions; a correct thread count with the wrong seed gives different numbers. Figure 3 shows why only the correct combination recreates the original arrangement.
On real chips, the thread counts are much larger, but the principle is the same. In the NVIDIA configurations examined here, the Hopper H100 SXM, H200 and H800 have 132 SMs and use 270,336 threads; the Blackwell B200/B300 have 148 SMs and use 303,104 threads; and the Blackwell GB200/GB300 have 152 SMs and use 311,296 threads. Recovering the thread count therefore tells us which of these hardware groups matches the starting arrangement, although it cannot distinguish chips within a group. A Hopper match, for example, cannot tell an H800 from an H100 or H200.
The question is whether enough of that arrangement survives training for us to recover it. Some weights, such as those reserved for words or symbols never encountered during training, can remain untouched and retain their starting values almost exactly. We can compare these preserved values directly with the starting values generated by a candidate seed and thread count. Figure 4 shows such a comparison: DeepSeek-V3’s preserved weights match the Hopper arrangement, while DeepSeek-V4-Flash’s match the Blackwell arrangement.
Even weights that training has changed can retain a faint trace of their starting values. Each final weight is its starting value plus all the adjustments made during training. If those adjustments do not completely cancel or overwhelm the starting differences, some of those differences survive. For example, two weights that begin at 0.2 and 0.8 and each increase by about 0.1 will still be ordered the same way afterward. Real adjustments vary much more, so one weight tells us little. But across hundreds of thousands of weights, we can test whether higher starting values still tend to correspond to higher final values. Figure 5 shows this weak but measurable relationship. It is a finding in these weights, not a property guaranteed to survive every training run.
These surviving traces let us work backward. Suppose, in an invented example using Figure 1’s layout, seed 7 makes the first thread produce 0.2, −0.5 and 0.8. With 48 threads, those values go into positions 1, 49 and 97; with 40 threads, they go into positions 1, 41 and 81. If the published weights preserve the first pattern, we can try candidate seeds and thread counts until we recreate it. In the actual investigation, we compare thousands of values in their corresponding positions. Untouched weights can match exactly; trained weights may show only the weaker resemblance described above. In either case, we look for the combination that best reproduces the surviving pattern.
We then test that combination on weights we kept out of the search. Having chosen a seed and thread count using one set of weights, we use them to predict the starting values of a different set, without changing either setting to improve the fit. A match on these previously unused weights is stronger evidence than a match confined to the weights that helped us choose the combination. Figure 6 shows the comparisons: DeepSeek-V3 matches the initialization layout of Hopper H100 SXM, H200 or H800 chips; DeepSeek-V4-Flash matches Blackwell B200/B300; and Kimi K3 matches Blackwell GB200/GB300.
In our investigations, we found patterns strongly suggestive of initialization on Blackwell chips in six models from four Chinese companies: DeepSeek-V4-Flash and DeepSeek-V4-Pro from DeepSeek, Kimi K3 and Kimi K3.1-Pro from Moonshot AI, MiniMax-M3 from MiniMax, and Ling-3.1-flash from Ant Group. V4-Flash and MiniMax-M3 match the 148-SM layout; the other four match the 152-SM layout. These are fingerprints of the starting weights, which support, but do not by themselves prove, the use of Blackwell chips for training AI models.
Limits of our investigation
Notably, the forensic method we used to identify the hardware on which these models were initialized only works for certain models. It needs published weights, so closed models cannot be checked. It also needs a recognizable, hardware-dependent pattern from the software that generated the starting weights. PyTorch on the GPUs examined here leaves such a pattern; Baidu’s PaddlePaddle framework, which was used to train Baidu’s ERNIE-5.5 model, does not. We were able to recover the seed for ERNIE-5.5 (2760), but could not identify which hardware was used to initialize it. Likewise, weights initialized on an ordinary processor rather than a GPU leave no GPU fingerprint; several of Alibaba’s Qwen3 models were initialized this way, and thus leave no trace of which GPUs were used to train them. We also found no fingerprint in Meituan’s LongCat-2.0, which the company says was trained on “AI ASIC superpods,” or in DeepSeek-V4.1-Flash, despite an exhaustive search.
The method identifies the hardware that generated the starting weights, not every chip that later helped train the model. When a training run creates its weights on the same GPUs that will train it, the fingerprint points to both. But a lab could generate the weights on one system and move them to another, or continue training an existing model on new hardware. The weights alone cannot rule out those possibilities. A mixed cluster introduces the same limitation. If NVIDIA chips generated some weights and Huawei chips later helped train them, the NVIDIA pattern could survive without revealing Huawei’s participation. Different NVIDIA generations could leave different patterns in the parts they initialized, if those traces survived. In Kimi K3, at least 64 separately seeded processes each left the same 152-SM layout. A Blackwell-compatible pattern therefore supports its use at initialization, subject to the AMD alternative below; it does not establish that the entire training run used Blackwell. A Hopper pattern likewise does not rule out later training on Blackwell.
The weights also cannot reveal who owned the chips or where they were located. Blackwell systems can be rented from data centers outside China. The evidence concerns access to the hardware; by itself, it does not establish that chips were smuggled into China or that an export-control violation occurred.
Could a different chip produce one of these Blackwell-compatible patterns? Among the NVIDIA configurations tested here, the older chips cannot: software can use fewer of a chip’s processing units, but cannot give it more than it physically has. Under the standard PyTorch behavior examined here, they cannot produce the 148- or 152-SM layouts. The China-market Blackwell graphics cards use a different number of threads per SM and do not produce either total.
AMD presents a different possibility. An MI300X normally uses 304 processing units, but it can be divided into two groups of 152 or configured to use only 148. Its random-number software can also generate the same underlying sequences as NVIDIA’s. Such configurations would be very unusual, but we confirmed on a physical MI300X that, limited to 152 or 148 of its units, it reproduces the layouts we associate with Blackwell, so the layout alone does not settle the question.
To distinguish them, we looked for small numerical differences in the values themselves. AMD and NVIDIA perform one calculation in the number-generating process slightly differently. On a physical MI300X, DeepSeek-V4-Flash’s preserved weights point to NVIDIA: in the 377 values where the two vendors’ results differ, the published weight matches NVIDIA’s in 363 and AMD’s in none. The same test could not settle the other five models, but we consider the AMD explanation very unlikely for them. In its normal configuration, an MI300X produces neither layout; a lab would have had to configure an entire cluster to use the same number of processing units as a Blackwell chip. Other public evidence also points to Blackwell: U.S. officials and press reports have alleged that DeepSeek and Moonshot AI were using Blackwell chips, and Ant Group’s public code includes benchmark results generated on a GB300.
Verifying our findings
To reproduce the result that linked DeepSeek-V3 to Hopper and DeepSeek-V4-Flash to Blackwell, we ran unmodified PyTorch on a Hopper-class NVIDIA H100 and a Blackwell-class NVIDIA B300. We had identified DeepSeek’s seed number as 953049583, and found that it was used in the initialization of both DeepSeek-V3 and DeepSeek-V4-Flash. Using that seed, the H100 reproduced the preserved starting values in DeepSeek-V3, but not V4-Flash; the B300 reproduced the preserved values in V4-Flash, but not V3. On the B300, unmodified PyTorch reproduced 461 of the 469 selected rows in DeepSeek-V4-Flash with correlations above 0.99, including 445 entire rows that matched bit for bit. Eight selected rows were partly changed by training. On the H100, it reproduced all 57,344 preserved values in DeepSeek-V3 bit for bit. Neither chip reproduced the other model’s preserved rows. Changing the seed by one reproduced no matching rows on either ma