Silent data corruption (SDC) happens when hardware, such as a GPU, returns a wrong but plausible number and raises no error. In distributed training, the wrong number can flow into the gradients and weights of every replica. Loss can still look normal for hours, and by the time a team notices an unexplained divergence or a weaker model, the compute is spent. It happens at scale: during a 54-day period of Llama 3 405B pre-training on up to 16K H100 GPUs, Meta attributed 6 of 419 unexpected job interruptions to silent data corruption, and those were only the cases that interrupted the job and were traced to SDC.
Amazon SageMaker HyperPod already replaces nodes that report a fault: the health-monitoring agent watches for GPU errors, deep health checks stress-test nodes, and automatic node recovery swaps out bad hardware. SDC slips past all of these features, because the hardware never reports anything. Detection has to come from the training job itself.
In this post, we add three checks to a PyTorch DistributedDataParallel (DDP) training loop to detect SDC. When a check fires, we map the suspect rank to its node, contain the corruption, and have SageMaker HyperPod replace the node. Each check covers a different place where a fault can land:
- A non-finite gradient check catches NaN, Inf, and overflow in a GPU’s forward or backward pass, on the step it happens, and NaN or Inf that the gradient all-reduce introduces.
- A ring replay audit catches finite wrong values. On audit steps, every GPU recomputes a micro-batch from another node and compares the loss bit for bit and the gradients by fingerprint.
- A weight fingerprint comparison catches corruption in the optimizer step and in stored weights, by comparing every replica’s weights after the update.
We tested the checks with software-injected faults on a SageMaker HyperPod cluster with 4 ml.p5.48xlarge instances (32 NVIDIA H100 GPUs), and repeated every test on three instances, the minimum the checks need. The full code of this solution is available in the accompanying GitHub repository.
How silent data corruption happens and why the usual checks miss it
SDC comes from manufacturing defects (marginal transistors that slip past vendor screening) and silicon aging in a specific compute unit, most often a multiply-accumulate lane in a tensor core, which is exactly the hardware model training hammers. That marginal circuit computes correctly most of the time and wrong only under stress: high temperature, voltage droop, or specific operand patterns. Because the arithmetic logic path has no ECC or parity (unlike memory), the wrong result, say 4.0001 instead of 4.0000, is never flagged, and it flows through activations and gradients into every replica’s weights.
The reason it is so hard to catch is that SDC is in the compute path, and every integrity check you already have guards a different boundary:
| Check | What it guards | Why it misses SDC |
| ECC | memory | Catches bit flips in memory, not wrong math. There is no ECC on a tensor-core result. |
| Xid errors (NVRM) | GPU driver/hardware faults | The GPU raises an Xid when it detects a fault. SDC by definition raises none, so nothing lands in /aws/sagemaker/Clusters/ HMA logs. |
| DCGM deep health check | hardware faults | Misses defects that need your workload’s operands, thermal state, or timing. Runs on an idle node, outside your job. |
| NVLink / PCIe / EFA checksums | transport | Verify bytes arrived as sent, not that they were computed correctly. |
| Checkpoint checksums | storage round-trip | A poisoned-but-consistent checkpoint checksums fine. |
The way to catch SDC is to check the result of the computation itself.
Solution overview
The loop has four steps. Your training job does the first two, and the last two use Kubernetes and SageMaker HyperPod features:
Step 1. Detect: Three checks in your training loop name a suspect GPU by comparing data-parallel replicas.
Step 2. Localize: On SageMaker HyperPod clusters orchestrated by Amazon Elastic Kubernetes Service (Amazon EKS), the Kubernetes node name contains the instance ID, so mapping a suspect rank to a node is a lookup.
Step 3. Contain and correlate: Stop the job, cordon the node, and look at its GPU metrics in the SageMaker HyperPod observability dashboards.
Step 4. Confirm and recover: Confirm when the alarm is ambiguous, replace the node after review, and resume from a checkpoint saved before the suspect window.
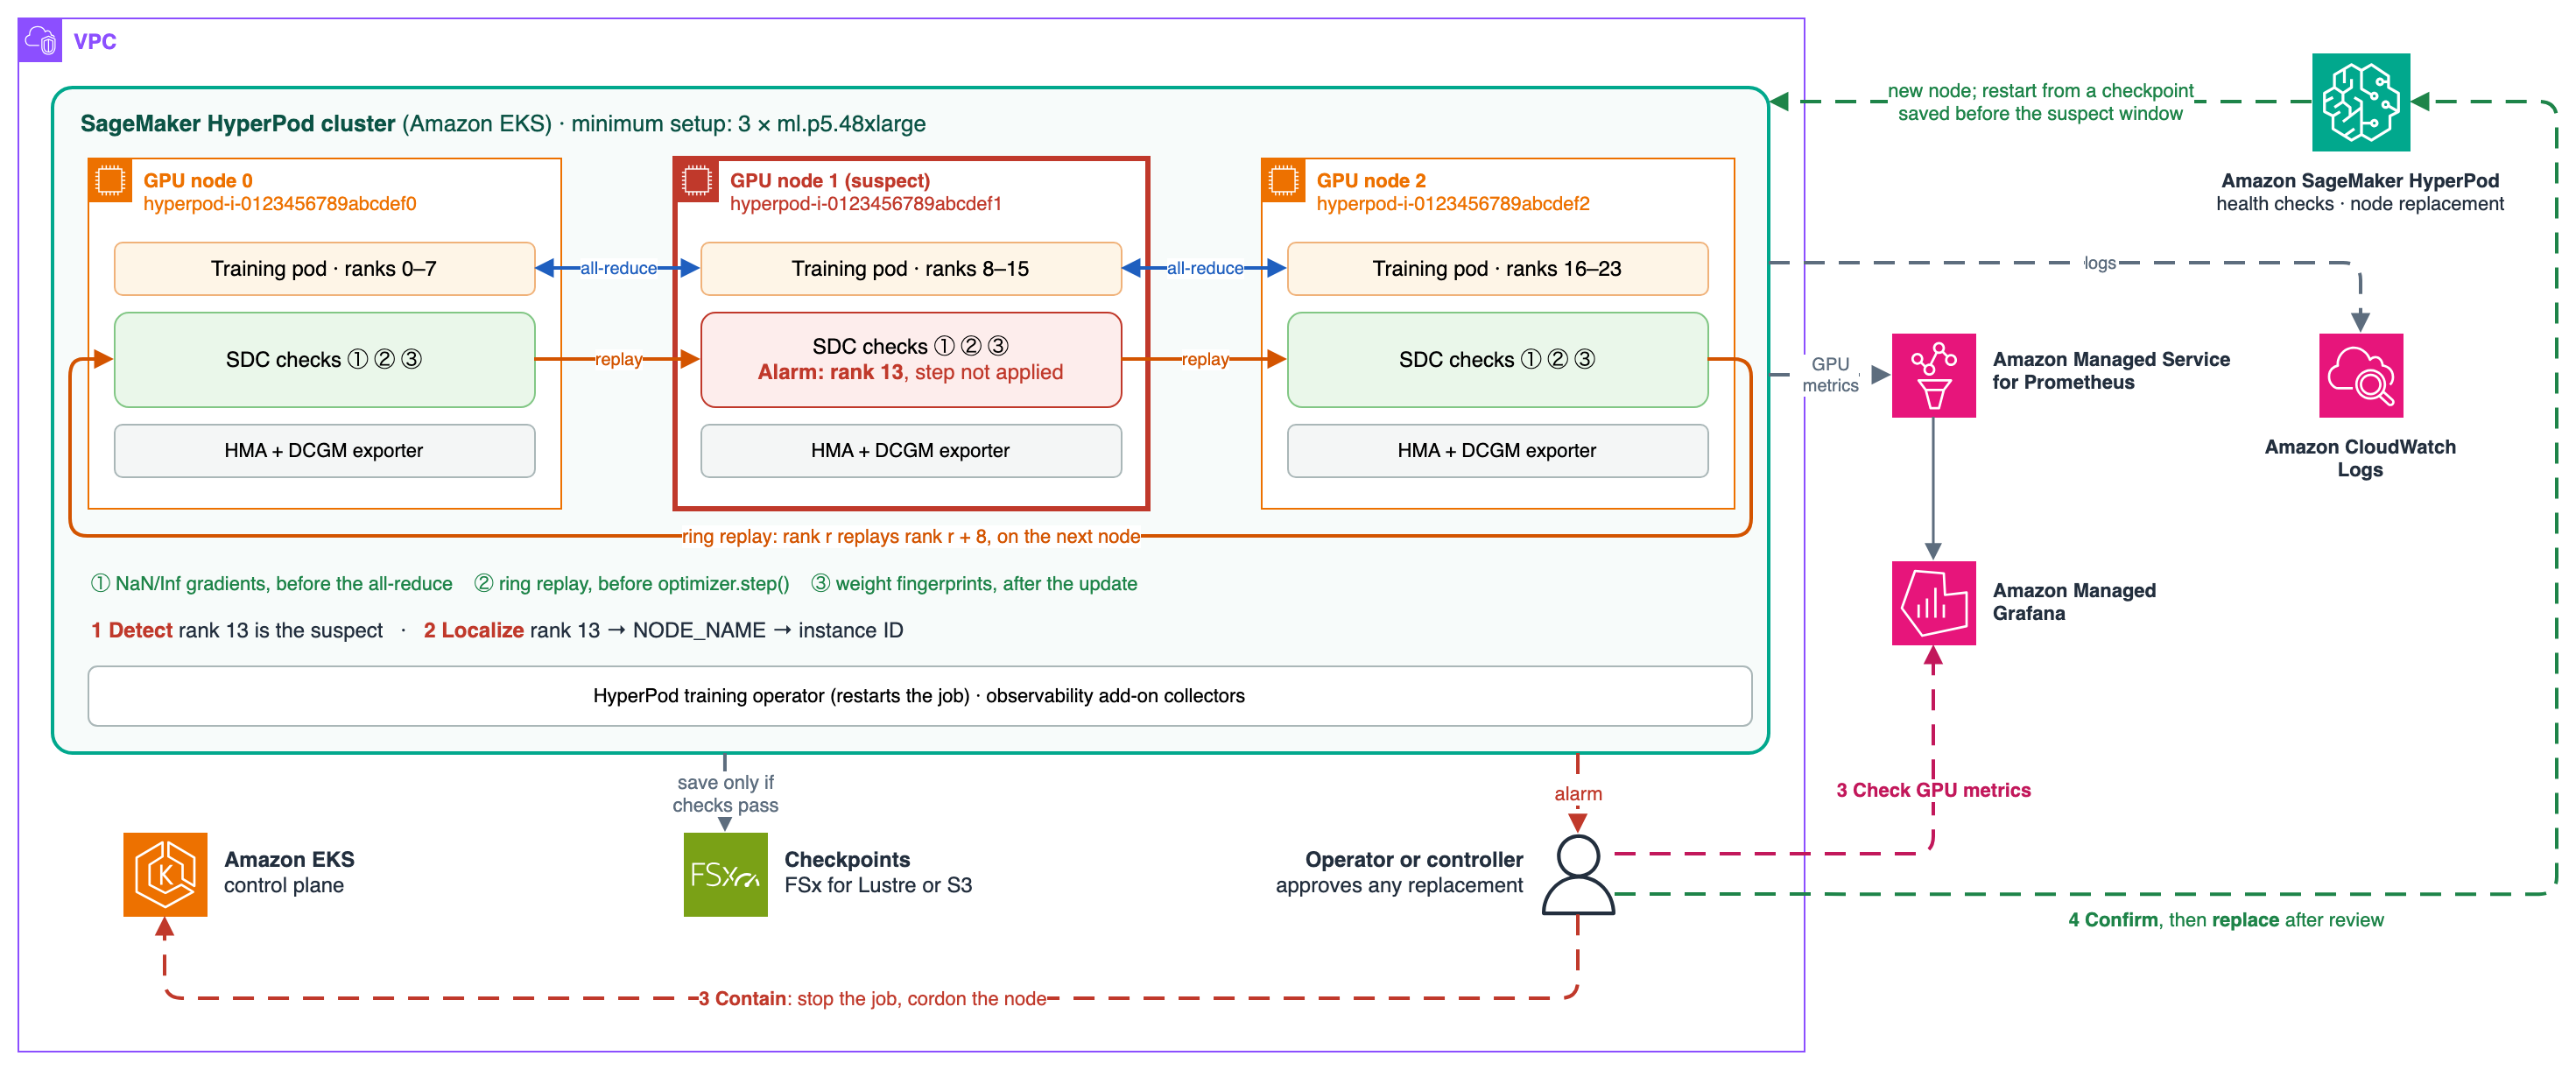
Figure 1: A SageMaker HyperPod EKS cluster with three p5 nodes running training pods and SDC checks. Node 1 raises an alarm for rank 13, and the proposed steps cordon the node, check GPU metrics, replace it, and restart training
It helps to see the loop as layers, each adding something different:
| Layer | Source | What it adds | Catches truly silent SDC? |
| 1. Non-finite gradient check | Your training script | Names a GPU whose local gradient is NaN or Inf, before the all-reduce, and stops the step if the reduced gradient is NaN or Inf | Only faults that become NaN, Inf, or overflow |
| 2. Ring replay audit | Your training script | Every GPU recomputes another node’s micro-batch and compares the loss bits and gradient fingerprints | Yes, for finite compute-path faults that change the loss or a gradient, on audit steps |
| 3. Weight fingerprint comparison | Your training script | Names a replica whose weights differ from a strict majority after the update | Yes, for optimizer-step and stored-weight faults on one copy. Blind to compute-path faults and to sharded weights |
| 4. Localization | Your training script, using SageMaker HyperPod node names | Maps a suspect rank to an instance ID from the Kubernetes node name | n/a: it localizes |
| 5. DCGM correlation | HyperPod observability add-on | The suspect GPU’s DCGM metrics around the alarm | It confirms faults only where they also appear in hardware counters. Clean telemetry doesn’t clear a node. |
| 6. Deep health check | StartClusterHealthCheck (DCGM L4) |
An on-demand hardware diagnostic on the suspect node | It catches hardware defects its own test patterns trigger. Triage, not proof |
| 7. Repeat-offender history | A query you build over retained alarms and telemetry | Nodes that alarm repeatedly | Partly: it surfaces nodes worth checking early |
Layers 1–3 are the only layers that detect silent SDC, and they live in your training code. Layer 4 turns their alarm into an instance ID, and the HyperPod layers corroborate the alarm and close the loop.
Prerequisites
To follow along, you need:
- A SageMaker HyperPod cluster orchestrated by Amazon EKS, with at least three GPU nodes. The ring audit needs three different nodes for every comparison it settles, and the weight comparison needs three copies of each weight to name the odd one out. See Orchestrating SageMaker HyperPod clusters with Amazon EKS.
- A PyTorch DDP training job in which every replica runs its own optimizer step, with a data pipeline that can rebuild any rank’s micro-batch for a given step, such as a seeded sampler.
- Checkpoints on shared storage, Amazon FSx for Lustre or Amazon Simple Storage Service (Amazon S3). Replacing a node destroys its root and secondary volumes, including anything on local NVMe.
- The SageMaker HyperPod observability add-on for the correlation step. Turn on advanced DCGM metrics if you want ECC, NVLink, and throttling counters.
- Access to the cluster through
kubectl, and AWS Identity and Access Management (IAM) permissions forsagemaker:StartClusterHealthCheckandsagemaker:BatchReplaceClusterNodes. See Manually quarantine, replace, or reboot a node.
Step 1: Detect with three checks in your training loop
Data parallelism trains several copies of the model, called replicas, at the same time. Each replica trains on a different slice of the batch. After each backward pass, an all-reduce averages the replicas’ gradients, and every replica applies that same average in optimizer.step(). Here’s one weight across three replicas, with a learning rate of 0.1:
| replica 0 | replica 1 | replica 2 | ||
| weight at start | 0.500 | 0.500 | 0.500 | same |
| local gradient | 0.20 | 0.40 | 0.30 | different (different data) |
| averaged gradient | 0.30 | 0.30 | 0.30 | same, after the all-reduce |
| weight after step | 0.470 | 0.470 | 0.470 | same |
Local gradients differ, because each replica sees different data. And after the optimizer step, the weights must be identical, bit for bit.
Where a fault lands decides which check can see it. If replica 1 computes a local gradient of 4.00 instead of 0.40, the all-reduce spreads that error to every replica: all three apply the same wrong update, and their weights still match. Only replica 1’s local gradient looked different, and only before the all-reduce. If instead replica 1 corrupts a weight during or after the optimizer step, its weights no longer match the others. There’s one exception: a NaN or Inf in one replica’s weights reaches every replica through the next all-reduce, and after that the replicas agree again. A fault inside the all-reduce itself, such as a GPU that adds a partial sum wrong, also reaches every replica identically.
So compute-path faults must be caught before the optimizer step, while the bad gradient can still be discarded, and faults in the update or in stored weights after it. Finite wrong values need recompute: comparing gradient norms across replicas catches only NaN and Inf (see Why not compare local gradient norms?). That gives three checks on every DP rank, in a fixed order within each training step:
- Non-finite gradient check – Before the all-reduce, flag any rank whose local gradient is NaN or Inf. This catches values that blow up in a GPU’s forward or backward pass, on the step they happen, and names the GPU. After the all-reduce, check the reduced gradient for NaN or Inf too, before the update.
- Ring replay audit – On audit steps, before the optimizer step, every rank recomputes the micro-batch of a rank on another node. It compares the loss bit for bit and, with deterministic kernels, every parameter’s gradient fingerprint. This catches finite wrong values in the compute path.
- Weight fingerprint comparison – After the optimizer step, every N steps and before every checkpoint, compare every replica’s weight fingerprints. This catches faults in the optimizer step and in stored weights.
The code in this step is for PyTorch DDP. For tensor, pipeline, or context parallelism, see Beyond DDP.
Order of execution
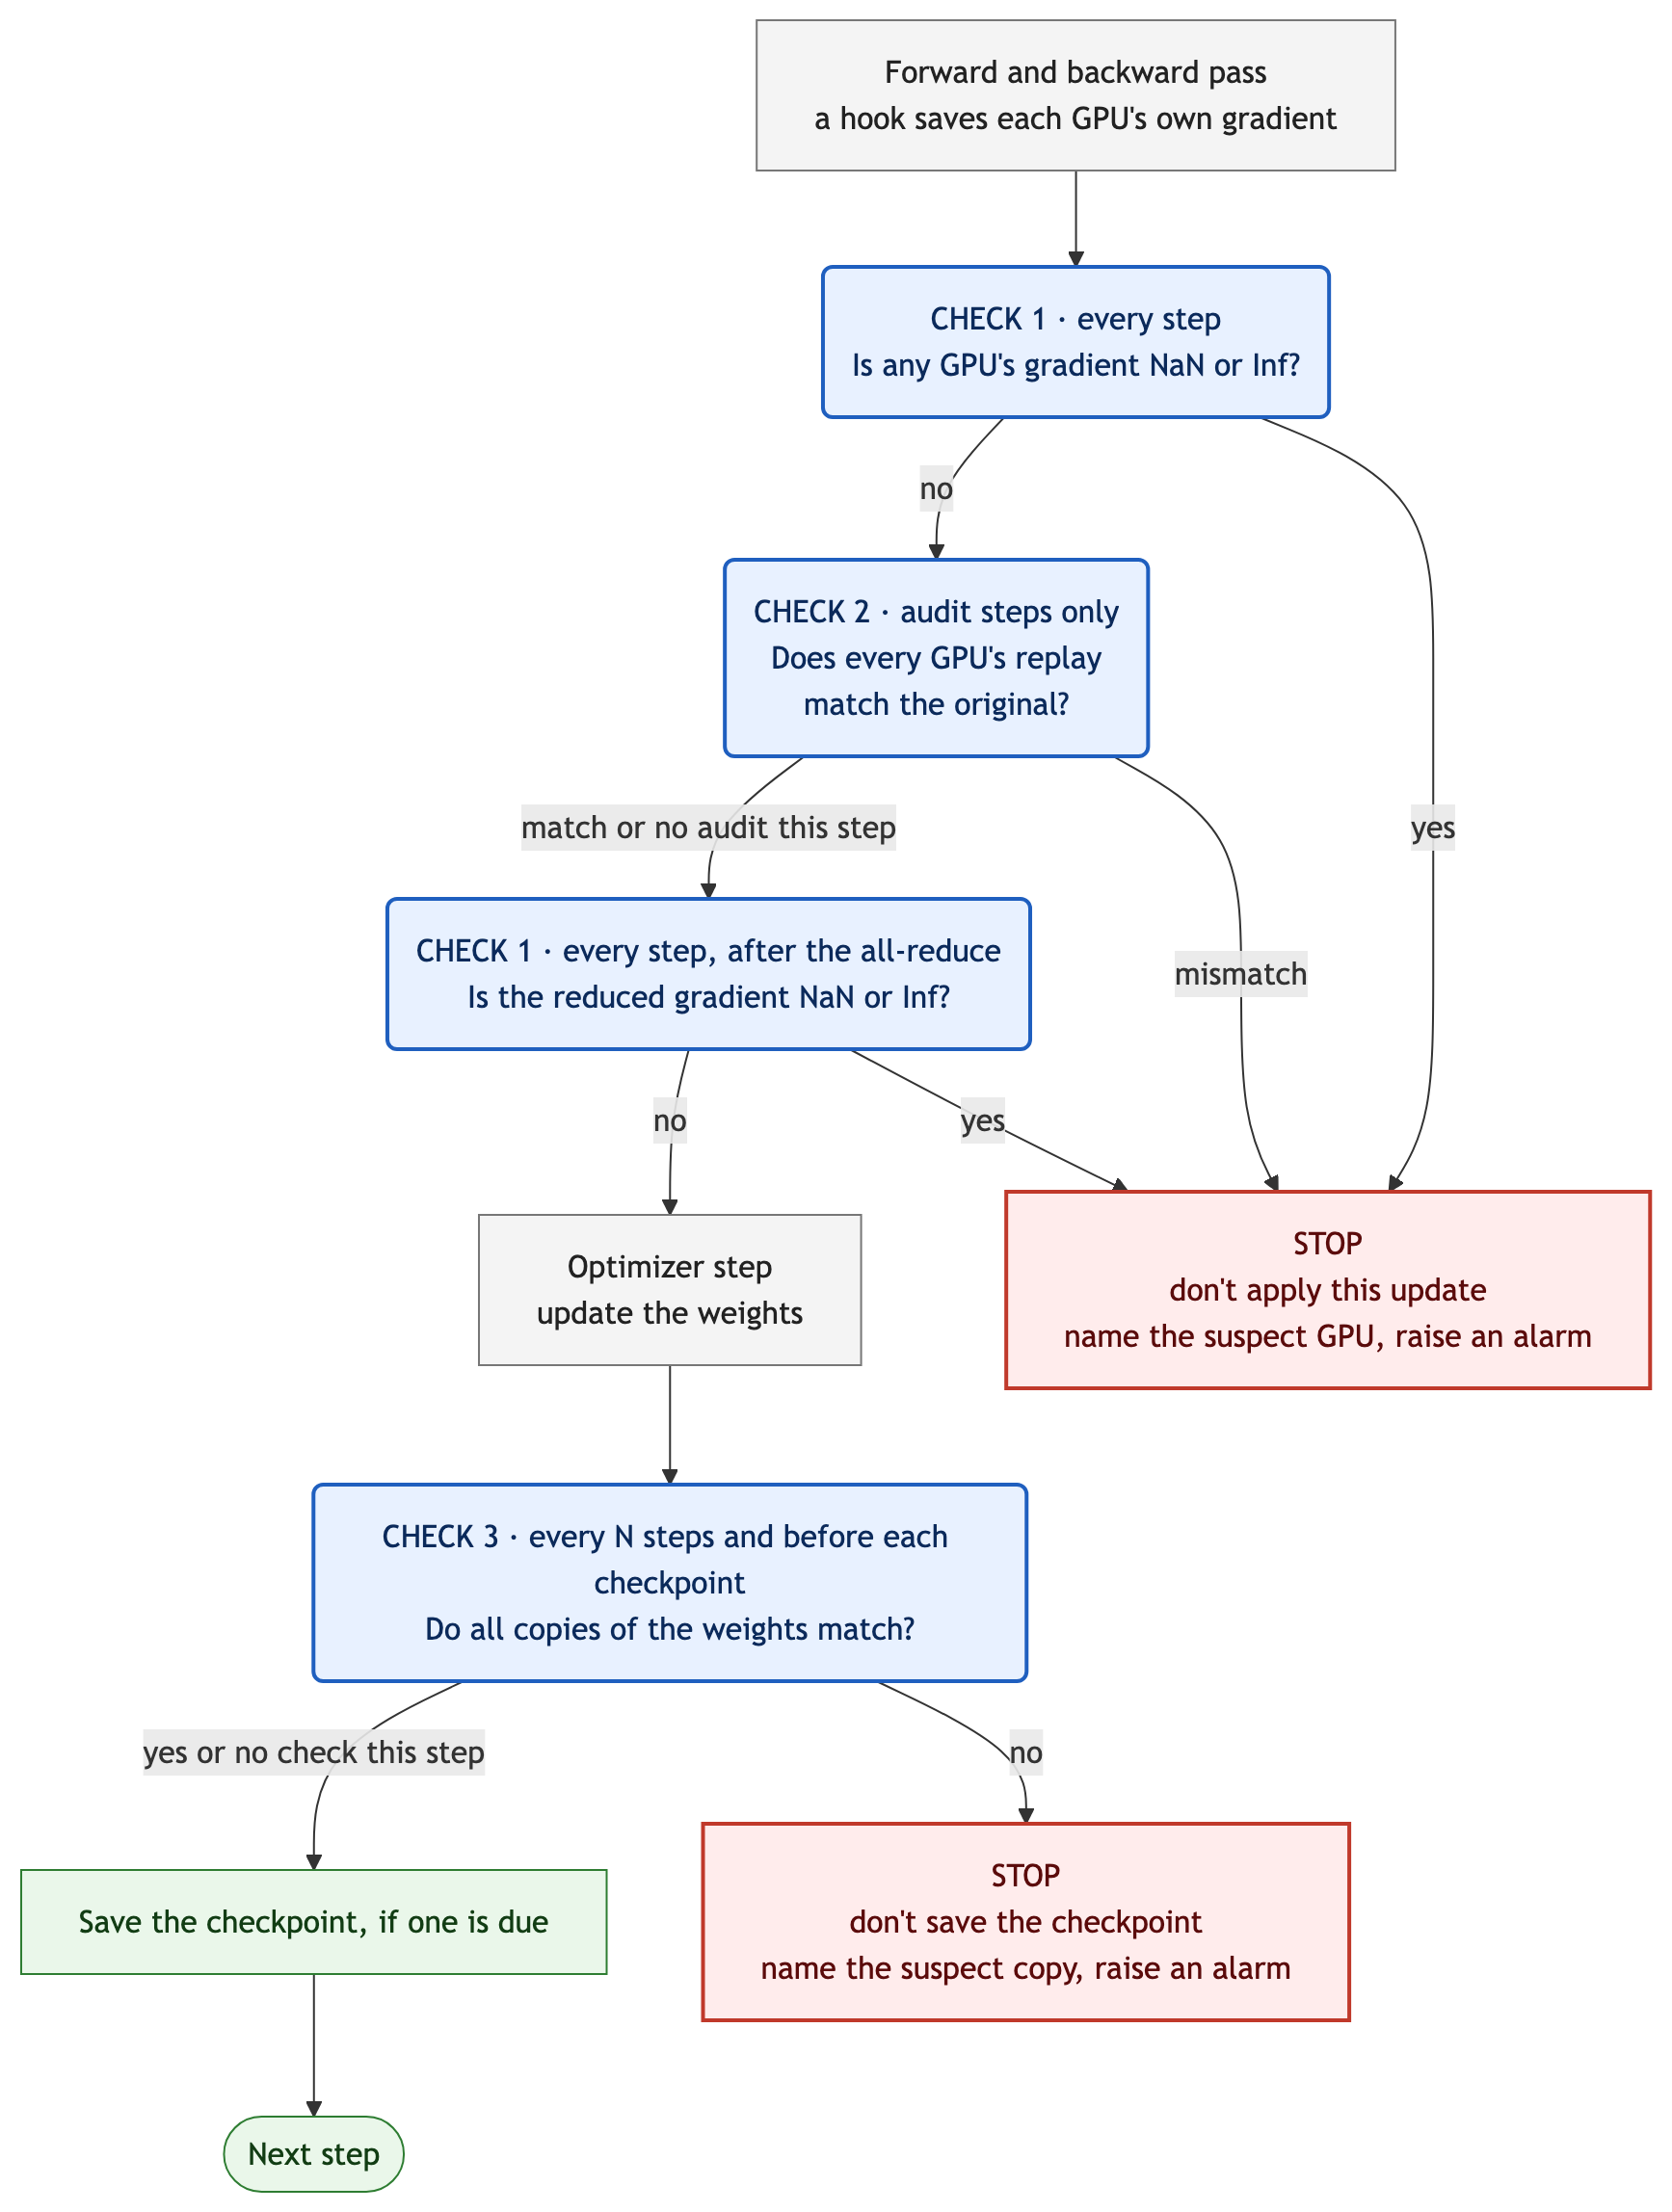
Figure 2: Flowchart of one training step. Check 1 (NaN/Inf gradients, before and after the all-reduce) and check 2 (ring replay, on audit steps) run before the optimizer step and stop the step if they fire. Check 3 (weight fingerprints) runs after it and blocks the checkpoint
Why not compare local gradient norms?
A natural first design, and the one we started with, flags a rank whose local gradient norm is more than k median absolute deviations (MADs) from the median of that step. We recorded every rank’s local gradient norm on every step of the three fault-free runs on 4 instances (22,800 steps, see Fault-free runs) on 32 H100s training a 953-million-parameter model, and the test doesn’t work:
- The healthy spread is too wide – Each rank sees different data, so healthy local norms already reached 224 MADs in the first 800 steps, and 1,240 MADs over all healthy steps.
- A quiet threshold sees nothing finite – At k = 336, 1.5 times the highest score in the first 800 healthy steps, it raised 11 false alarms in the remaining 22,000 healthy steps. And no finite fault came close: the faulty rank’s score never exceeded 6.9, even with one activation multiplied by 10,000.
Compare by fingerprint
Checks 2 and 3 compare tensors across GPUs. Sending whole tensors would cost too much, so each tensor is reduced to a fingerprint: two 64-bit sums of its raw bit patterns, one plain and one weighted by position. Any change to one or two elements of a tensor changes the fingerprint, for tensors with fewer than 2³² elements of up to 4 bytes each. That covers every weight fault we injected. Larger changes could, in principle, cancel out, so equal fingerprints are strong evidence of equal tensors, not proof. The position-weighted sum matters: in our tests, a swap of two weight values and a compensating change to two values left the plain sum unchanged, and only the weighted sum caught them.
_INT_VIEW = {1: torch.uint8, 2: torch.int16, 4: torch.int32, 8: torch.int64}

@torch.no_grad()
def fingerprints(tensors, chunk=1 << 24):
    # ... picks the device and allocates out: one row of two int64 per tensor
    for k, t in enumerate(tensors):
        if t is None:
            continue
        bits = t.detach().contiguous().view(-1).view(_INT_VIEW[t.element_size()])
        for i in range(0, bits.numel(), chunk):  # chunked to bound temporary memory
            b = bits[i:i + chunk].to(torch.int64)
            pos = torch.arange(i + 1, i + 1 + b.numel(), dtype=torch.int64, device=dev)
            out[k, 0] += b.sum()
            out[k, 1] += (b * pos).sum()
    return out
Check 1: NaN/Inf gradients, before and after the all-reduce
A DDP communication hook records each rank’s local gradient before it’s averaged. It stores the squared norm of every gradient bucket and, on deterministic audit steps, the fingerprints of every parameter’s gradient (used by check 2). Then it passes the bucket to PyTorch’s standard all-reduce.
After backward, nonfinite_ranks gathers one scalar from every rank and returns the ranks whose local gradient norm is NaN or Inf. The first rank flagged is the faulty one. If the step were applied, the NaN would reach every rank on the next step.
def local_stats_hook(stats, bucket):
    stats.sq.append(bucket.buffer().float().pow(2).sum())
    if stats.record_fingerprints:  # per parameter, before allreduce_hook divides in place
        rows = [stats.row[p.data_ptr()] for p in bucket.parameters()]
        stats.fp[rows] = fingerprints(bucket.gradients())
    return allreduce_hook(stats.dp_group, bucket)

def attach(ddp_model, dp_group):
    stats = LocalStats(dp_group, list(ddp_model.module.parameters()))
    ddp_model.register_comm_hook(state=stats, hook=local_stats_hook)
    return stats

def nonfinite_ranks(stats):
    """After backward: global ranks whose local gradient norm is NaN or Inf."""
    local = torch.stack(stats.sq).sum().sqrt().reshape(1)
    n = dist.get_world_size(stats.dp_group)
    gathered = [torch.empty_like(local) for _ in range(n)]
    dist.all_gather(gathered, local, group=stats.dp_group)
    bad = ~torch.isfinite(torch.cat(gathered).cpu())
    return [dist.get_global_rank(stats.dp_group, r) for r in bad.nonzero().flatten().tolist()]
train() also checks the gradient after the all-reduce. A NaN or Inf produced inside the reduction reaches every replica the same way, so the copies still match and check 3 passes them. Without this check, the NaN becomes NaN weights on every replica, and a checkpoint due on that step is saved with them and tagged as passing. clip_grad_norm_ already computes the norm of the reduced gradient, so the check adds only one one-element all-reduce per step. A finite error in the reduction still passes every check.
If you train with fp16 and a gradient scaler, exclu