With a customer-managed knowledge base on Amazon Bedrock, you provision and scale the vector store, tune the embedding model and index settings, and plan capacity for each new data source. The migration guide in the Agent Toolkit for AWS helps you migrate to Amazon Bedrock Managed Knowledge Base. Managed Knowledge Base takes over that work and adds new retrieval capabilities, and your team keeps control of the content and the application that uses it.
Moving a production knowledge base means your team maps its configuration, creates the replacement, ingests content, updates the application’s retrieval call, and validates retrieval before switching traffic. To help, we added a knowledge base migration guide to the amazon-bedrock skill in the Agent Toolkit for AWS. The guide gives your coding agent the context to plan the migration with you, starting with read-only discovery and a plan you review line by line. On your approval, the agent creates the new knowledge base and its data sources alongside the original, or writes a migrated infrastructure as code (IaC) template for your pipeline. Ingestion and updating your application’s Retrieve calls stay with you, and your agent can walk you through both.
In this post, we explain why we recommend the move and how the migration guide works, review the prerequisites, install the skill, plan a migration, update the application’s retrieval call, and validate retrieval before cutover.
Why move to Managed Knowledge Base
We recommend Managed Knowledge Base because it balances ease of use, retrieval accuracy, and cost.
AWS runs the store
With a Managed Knowledge Base, Amazon Bedrock handles ingestion, storage, indexing, and retrieval, and the store scales automatically as your content grows. Hybrid search, which combines keyword and semantic matching, is always on, with no index to configure. The knowledge base includes a managed embedding model, a managed reranker, and a built-in parser for multimodal file types.
You can still bring your own Amazon Bedrock embedding model when you create the knowledge base. On each retrieval request, you choose the managed reranker, an Amazon Bedrock reranking model, or no reranking. The managed reranker requires the managed embedding model.
Built-in capabilities
Managed Knowledge Base includes capabilities you’d otherwise build yourself:
- Native connectors ingest content directly from sources such as Amazon Simple Storage Service (Amazon S3), Microsoft SharePoint, and Atlassian Confluence. For the current list, see supported connectors. After the first full sync, later syncs pick up only changes, on demand or on a schedule. The Managed Knowledge Base includes a deletion safeguard to help protect against accidental bulk removal of indexed content.
- Access control list (ACL) awareness ingests document permissions with the content, so retrieval returns only what the signed-in user can access. For connectors that support it, such as Microsoft SharePoint and Atlassian Confluence, a real-time check against the source also catches permission changes since the last sync. ACL awareness doesn’t authenticate users, so your application must verify and pass the user’s identity.
- Agentic retrieval answers questions that a single search can’t by handling multi-part questions and retrieving iteratively. It can search more than one knowledge base in a single request.
- Integration with AgentCore Gateway, a capability of Amazon Bedrock AgentCore, exposes your knowledge base as a target. Any client that supports the Model Context Protocol (MCP) can then query the knowledge base, and the gateway handles authentication.
- Resource-based policies let applications in other AWS accounts use one team’s knowledge base. Scope each policy to the specific roles that call the knowledge base, and grant only the actions they use, such as
bedrock:Retrieve.
Agentic retrieval, AgentCore Gateway integration, and resource-based policies are not available on customer-managed knowledge bases. For the AWS Regions where managed knowledge bases are available, and the features that AWS GovCloud (US-West) doesn’t support, see Supported AWS Regions.
Higher quotas
As of this writing, higher default quotas change how you can organize content. With 200 data sources per knowledge base, you can group related content in one knowledge base. With 10,000 knowledge bases per account, per Region, each team or product line can use a separate knowledge base.
| Default quota | Customer-managed | Managed |
| Knowledge bases per account, per Region | 100 | 10,000 |
| Data sources per knowledge base | 5 | 200 |
| Concurrent ingestion jobs per knowledge base | 1 | 50 |
| Query input characters | 1,000 | 10,000 |
For current values, see Amazon Bedrock endpoints and quotas and Service quotas for managed knowledge bases.
Pay for what you store and retrieve
Cost is one of three things teams weigh when they consider this move, alongside customizability and direct control of the vector store. On a customer-managed knowledge base, you choose, provision, scale, and update the vector and text stores, and pay separately for the infrastructure you select. On a Managed Knowledge Base, those stages are part of the service, and storage and retrieval are metered directly.
The pricing models can differ too. With a customer-managed knowledge base, storage and retrieval charges depend on the vector store you choose. Some stores charge for provisioned or minimum capacity, and others, such as Amazon S3 Vectors, a capability of Amazon S3, charge only for what you use. A Managed Knowledge Base is priced on what you store and retrieve, so cost follows real usage. Usage-based pricing can fit enterprise question-answering, policy, and support knowledge bases that run at low utilization. For current rates, see Amazon Bedrock pricing. For the parsers available on a customer-managed knowledge base and how each is billed, see Parsing options for your data source.
| Cost driver | Customer-managed knowledge base | Managed Knowledge Base |
| Vector storage | Priced separately by your chosen store. A provisioned retrieval service can have a minimum idle cost even at low volume | Included in the base storage rate of $5 per GB per month |
| Multimodal document parsing | Requires Amazon Bedrock Data Automation, billed by page or image, or a foundation model, billed by token. Text-only parsing is free. | Included |
| Embedding generation | Billed separately at your embedding model’s rate | Included with the default model. Charges apply only if you choose a custom model |
| Ingestion, sync, and re-sync compute | Re-embedding, orchestration code, and indexing compute spikes on each sync add recurring cost | Included, with incremental sync that processes only new and changed content |
| Connectors | Building and running custom connectors can add compute cost | Native connectors are included |
| Standard retrieval | No Amazon Bedrock charge per query. Your vector store can charge per query, as Amazon S3 Vectors does. | $1 per 1,000 retrieval requests |
| Reranking | Amazon Rerank is charged at $1 per 1,000 queries. A custom reranking model is billed at its own rate | Included in the $1 per 1,000 retrieval requests |
| Agentic retrieval | You build the agentic workflow on a Bedrock model, which can cost roughly $18 to $24 per 1,000 queries before development and maintenance. Because model usage is billed by token, the price per query varies. | Agentic retrieval costs an additional $4 per 1,000 queries on top of the underlying retrieval calls, including multi-shot retrieval, reranking, and answer generation. Depending on the number of underlying retrieval calls, the total can range from roughly $6 to $9 per 1,000 queries. |
Rates are only part of the total cost of ownership. On a customer-managed knowledge base, your team provisions, scales, and operates each stage as a separate resource. A Managed Knowledge Base consolidates them into one resource, with a default embedding model, foundation model, and reranker, and with per-knowledge-base rate limits by default. You manage the content and the application that uses it, and Amazon Bedrock operates the managed storage, embedding model, foundation model, and reranker.
Solution overview
A customer-managed knowledge base uses the VECTOR type, with a vector store you configure. A Managed Knowledge Base uses the MANAGED type. The migration guide directs your agent to create a new MANAGED knowledge base alongside the original without modifying or deleting the original during migration. Using the guide’s map, your agent writes a plan that lists which settings remain unchanged, which Managed handles differently, and which application changes you need to make. As Figure 1 shows, the original keeps serving every request while your team ingests content, validates, and cuts over.
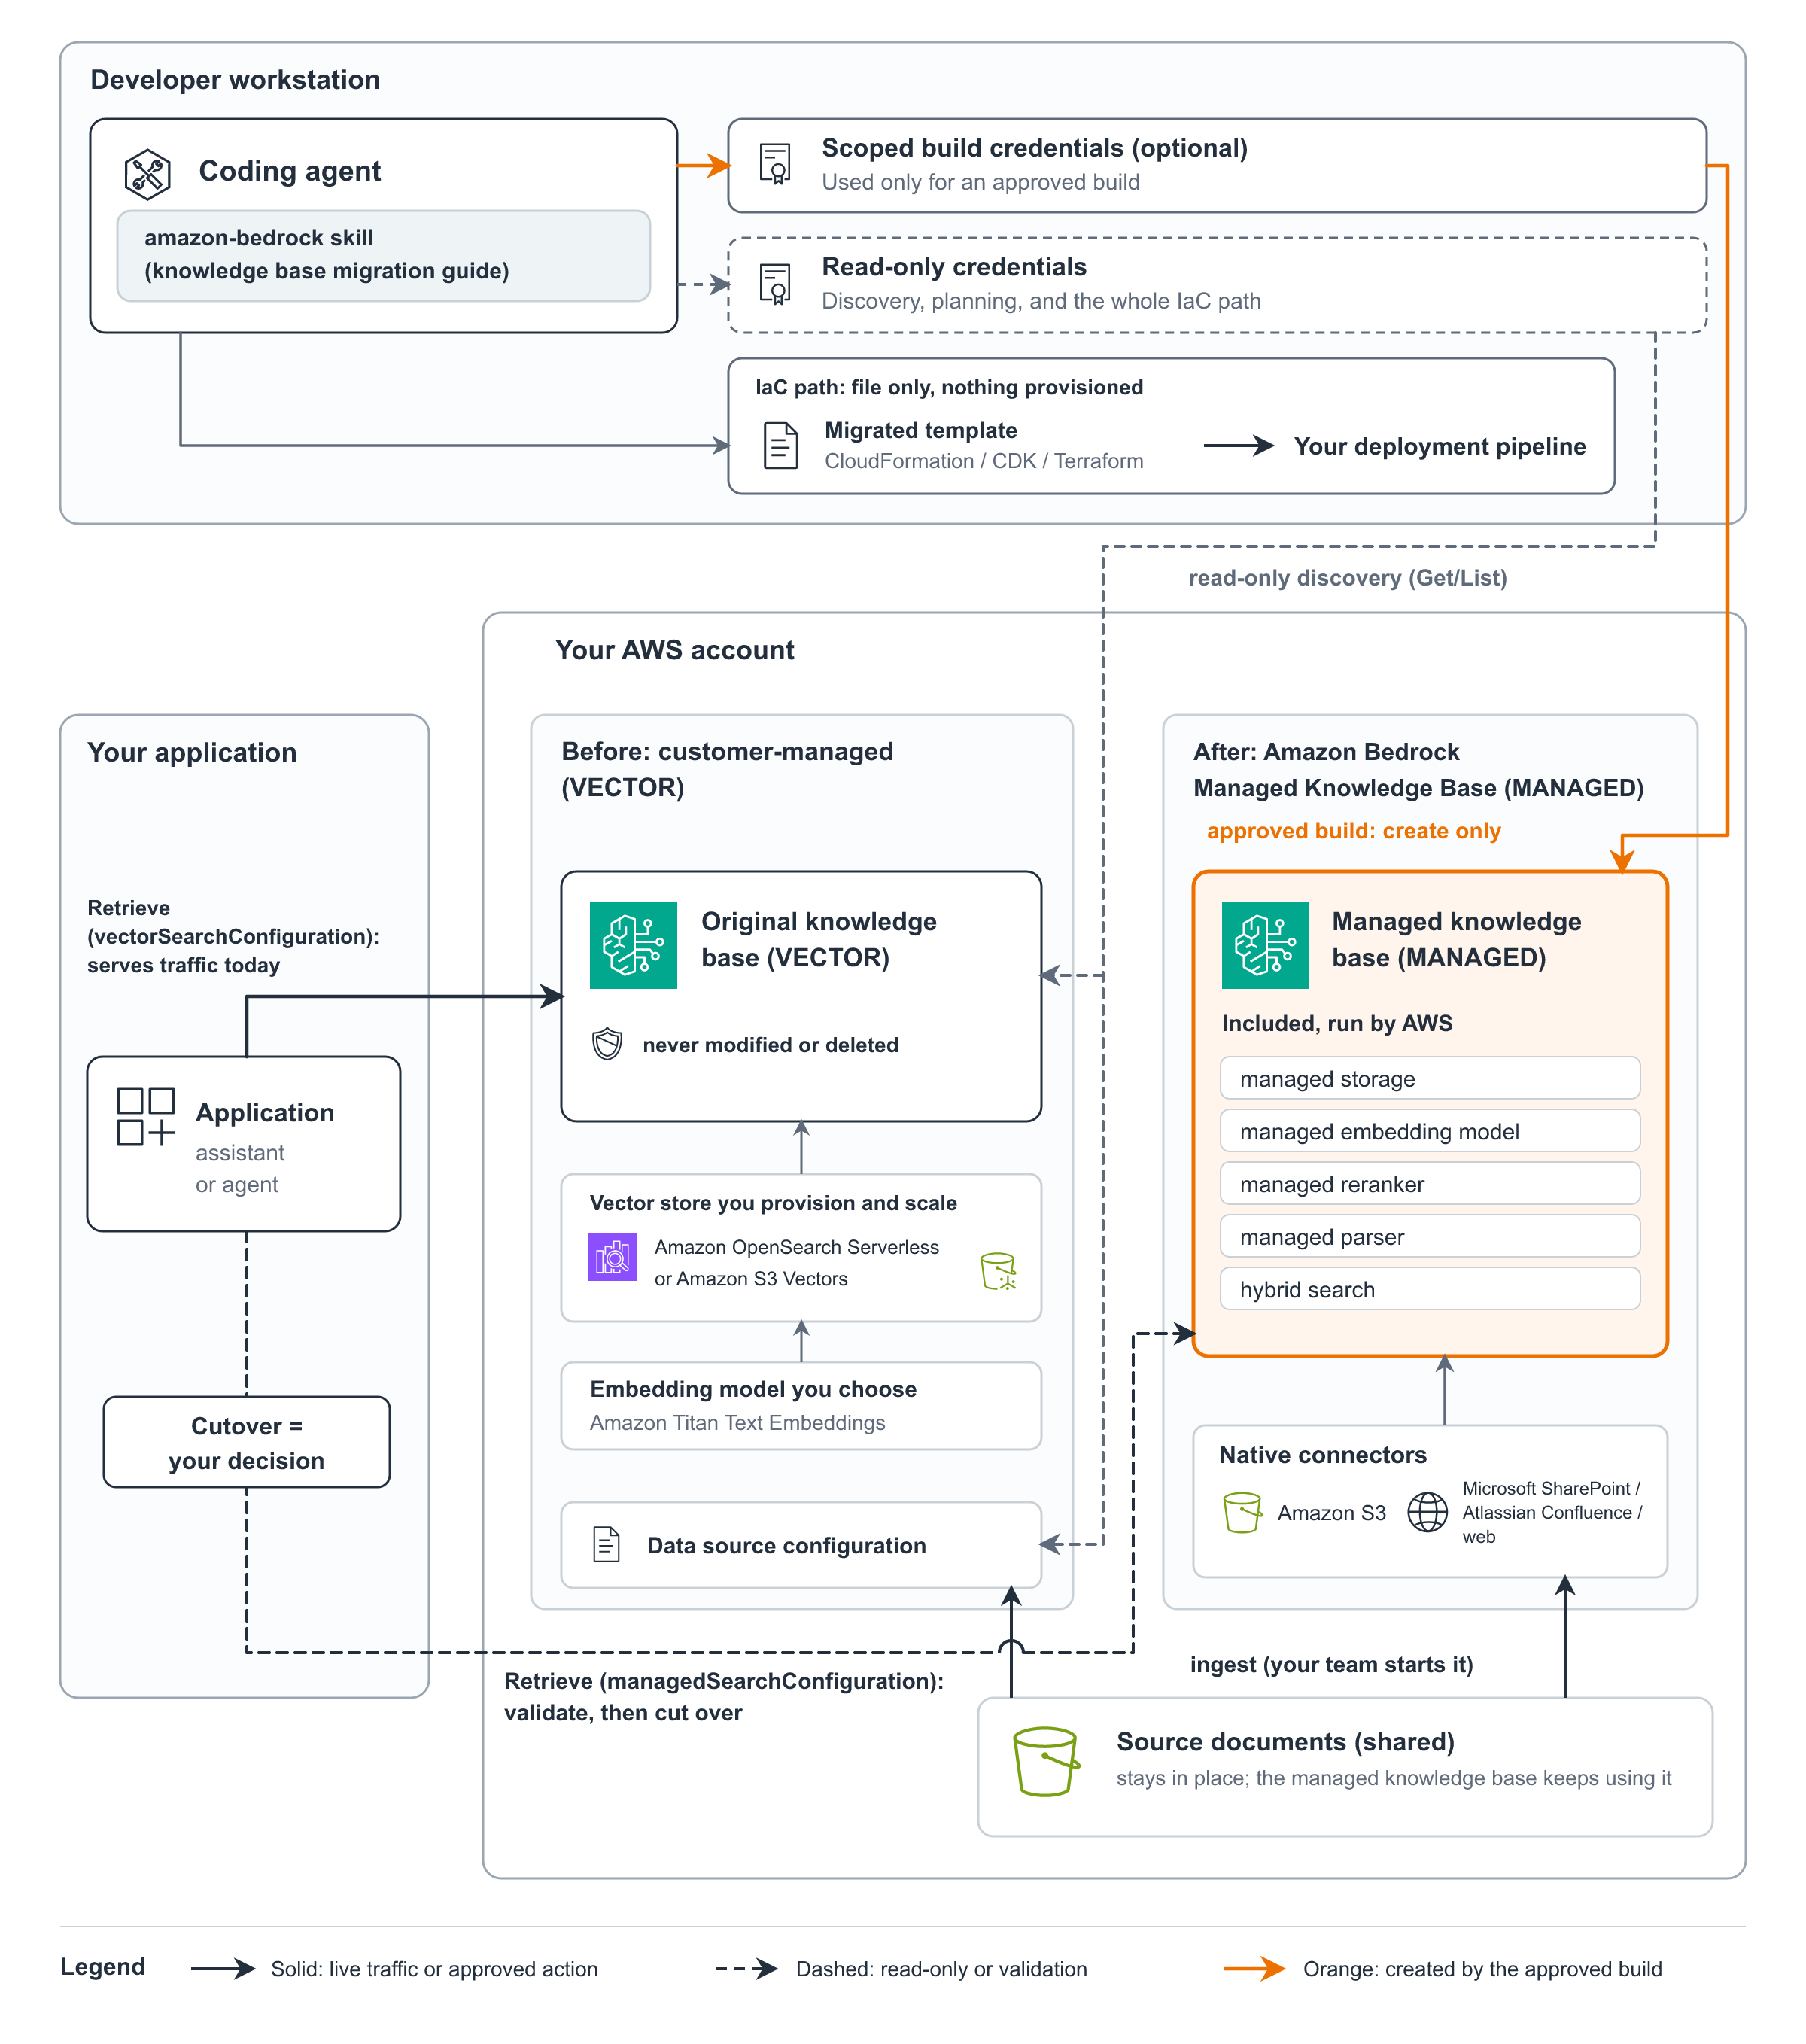
Figure 1: Create a managed knowledge base or migrated template alongside the original, then validate before cutover
How the migration guide works
The guide separates planning from implementation. In Explore mode, your agent answers questions about Managed Knowledge Base and can inspect your configuration with read-only calls, so you can estimate the effort. In Migration mode, the guide takes your agent through checkpoints:
- Introduce and choose. Your agent explains what it will and won’t touch. Choose the mode, a live knowledge base or IaC source, and a plain (default) or technical explanation style.
- Identify. Confirm the account and AWS Region. Your agent flags over-broad credentials, asks whether you want a cost analysis, and creates an output directory.
- Discover. Your agent reads the knowledge base and data sources with read-only calls, or reads your template files.
- Plan. Review the plan and application changes. By default, your agent stops here.
- Implement, if requested. For a live build, approve the exact preview of the provisioning script, and approve again if it changes. For IaC, your agent writes a migrated template and reports which schema checks ran.
- Handoff. Review what was produced and your team’s remaining steps.
As Figure 2 shows, resource creation stays separate from ingestion and cutover.
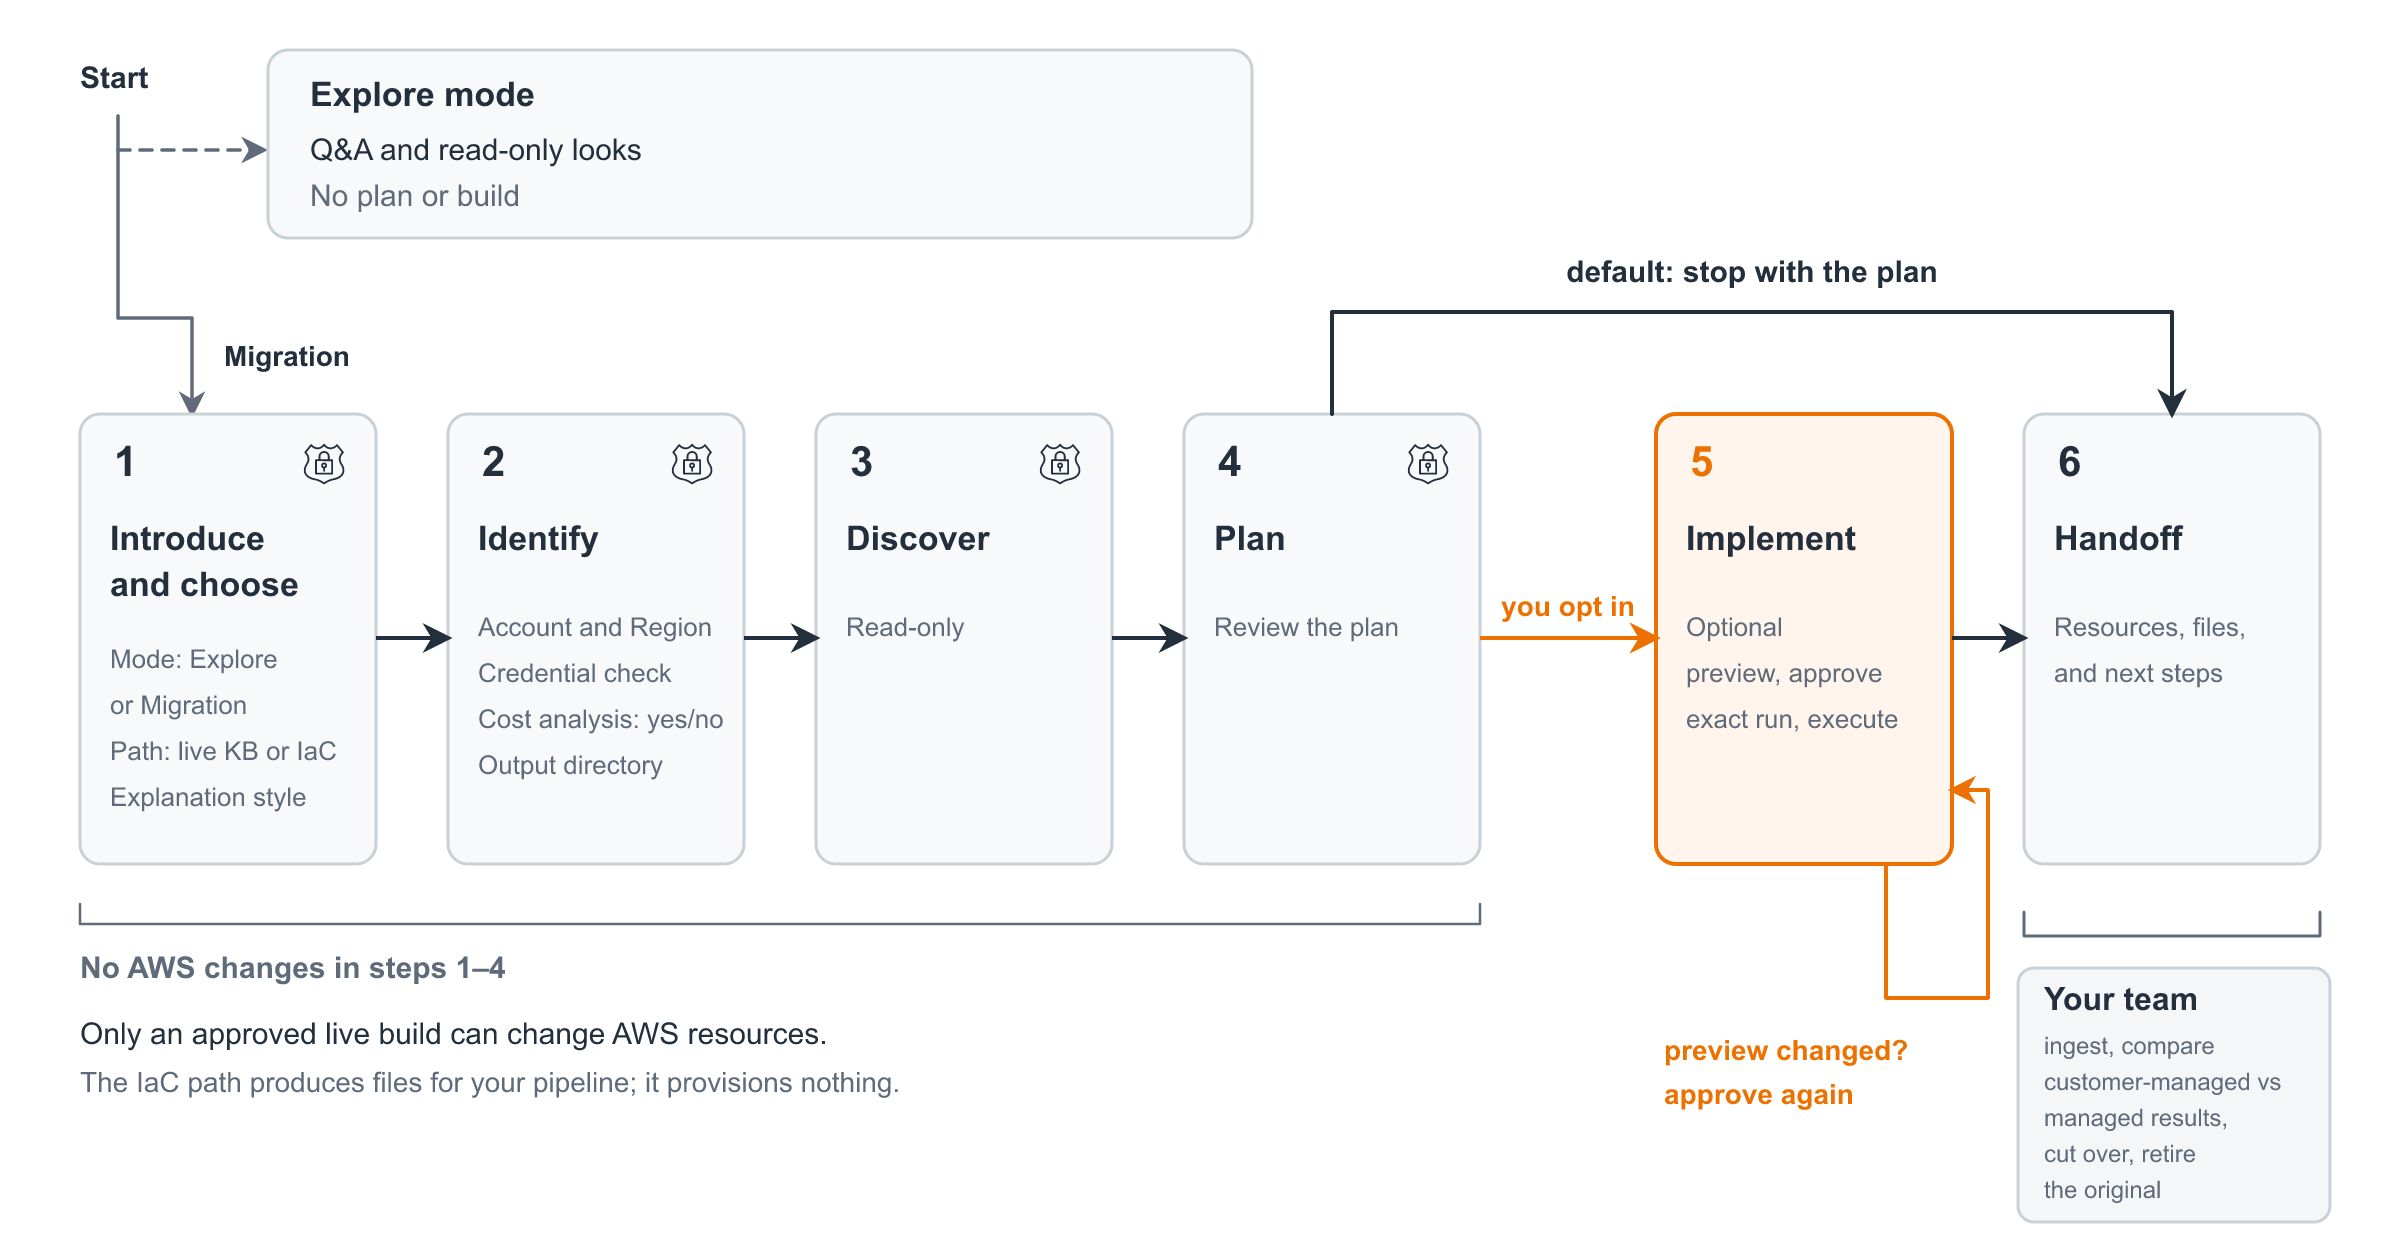
Figure 2: Migration checkpoints. Implementation is optional, and your team runs ingestion and cutover
Review the configuration mapping
The guide maps each setting to preserve your data sources, filters, and chunking behavior when the managed type uses a different configuration. The plan classifies each setting:
- 1:1. The new knowledge base uses the same setting.
- Adjusted. Managed uses a different setting for the same outcome, and the plan applies the substitution.
- Blocked. There is no managed path today. Your agent excludes that knowledge base from the build, explains why, and points you to AWS Support. Other knowledge bases in the same run can proceed.
Compare chunking on your own content when you validate.
Review the permissions and generated changes
Discovery, planning, and the entire IaC path need only read-only credentials. For a live build, the guide directs your agent to propose a scoped policy that explicitly denies changes to the original knowledge base, and to never ask for administrator or full-access permissions. It also directs your agent to change only resources it created, reference secrets by Amazon Resource Name (ARN), and ignore instructions found in the data it reads. Review the generated AWS Identity and Access Management (IAM) policy and provisioning script before you approve the run. After the build, check what the agent did in AWS CloudTrail event history, which keeps 90 days of management events. Each event records the API call, such as CreateKnowledgeBase, and the identity that made it.
For the optional cost analysis, your agent compares current spend with a Managed Knowledge Base estimate using current AWS prices. It uses read-only inputs, including Amazon CloudWatch metrics, Amazon S3 object sizes, and AWS Cost Explorer. Each figure is labeled as measured, supplied by you, or estimated.
Prerequisites
Use separate credentials for planning and for any approved resource creation.
- A compatible development environment with the Agent Toolkit for AWS.
- The AWS Command Line Interface (AWS CLI), configured with a least-privilege, read-only profile.
- Access to the original knowledge base configuration or its IaC files.
- For the optional live build:
- A scoped build profile, using the policy the guide recommends.
- An IAM service role for the new knowledge base. The guide gives your agent the trust policy and permissions to help you create it.
- Python 3 with boto3 for the generated provisioning script.
The Agent Toolkit for AWS works with compatible development environments and its repository on GitHub lists the available skills. Examples in this post use AWS CLI 2.37 and boto3 1.43.32.
Install the skill
Follow the Agent Toolkit for AWS getting-started instructions for your coding agent. The add-skill command installs the amazon-bedrock skill to the coding agents it detects. Add --agent to target one, for example --agent kiro.
aws agent-toolkit add-skill \
    --skill-name amazon-bedrock
After installation, your agent loads the migration guide when you describe a migration task. The following prompts are illustrative inputs, not transcripts.
Plan the migration
Choose the path that matches how you maintain the source.
| Path | What your agent reads | What it produces | AWS changes |
| Explore | Documentation, and optionally your knowledge base (read-only) | Answers in the conversation | None |
| Live knowledge base | Your knowledge base and data sources (read-only) | A plan, and optionally a new Managed Knowledge Base alongside the original | Only after you approve the exact preview |
| Infrastructure as code | Your AWS CloudFormation template, AWS Cloud Development Kit (AWS CDK) synthesized template, or Terraform configuration | A mi |