In my previous post: Building persistent memory for multi-agent AI systems with Amazon S3 Vectors, we explored why memory engineering is the foundational discipline for production multi-agent systems. We showed how Amazon S3 Vectors, a capability of Amazon Simple Storage Service (Amazon S3), meets the architectural requirements for agent memory: semantic retrieval, rich metadata, strong consistency, and elastic scale.
In this post, we move from architecture to implementation. We show you how to use Amazon S3 Vectors as the persistent memory layer within the NVIDIA NeMo Agent Toolkit (NAT), deployed on Amazon Elastic Kubernetes Service (Amazon EKS) for full operational control.
By the end of this post, you will understand how NAT’s memory subsystem works and how to implement Amazon S3 Vectors as a custom memory provider. You will also learn how to deploy the stack on Amazon EKS, using a multi-agent investment research use case as the running example.
What is NVIDIA NeMo Agent Toolkit?
NVIDIA NeMo Agent Toolkit (NAT) is an open source framework for building, profiling, and optimizing AI agents. It’s framework-agnostic, working with Strands Agents, LangChain, LlamaIndex, CrewAI, and custom implementations. NAT provides four capabilities relevant to production agent systems:
- Agent orchestration – Define agents as composable workflows with configurable large language models (LLMs), tools, and prompts. You run them locally with
nat runor as persistent services withnat serve. - Profiling – Track token usage, latency, throughput, and run times across agents and individual tools to identify bottlenecks in multi-agent workflows.
- Evaluation – Built-in evaluators for answer accuracy, context relevance, response groundedness, and agent trajectory, with support for custom evaluators.
- Optimization – Automated hyperparameter tuning (temperature,
top_p,max_tokens) that maximizes quality while minimizing cost and latency.
NAT’s memory module
NAT includes a dedicated memory subsystem designed to store and retrieve conversation history, user preferences, and long-term knowledge across agent invocations. The memory module is extensible: you create custom memory providers (backends) by implementing NAT’s plugin interface. Key components include:
MemoryEditor– The abstract interface that all memory backends must implement. It defines three methods:add_items(),search(), andremove_items().MemoryItem– The data model representing a piece of memory, containing fields for conversation history, tags, metadata,user_id, and an optional textual memory string.MemoryBaseConfig– A Pydantic base class that custom memory configurations extend. NAT discovers providers via the_typefield in its YAML config.- Automatic memory wrapper – The
auto_memory_agentworkflow type that wraps agents with automatic memory capture and retrieval, without requiring the LLM to explicitly invoke memory tools.
NAT currently has these built-in memory providers: Mem0, MemMachine, Redis, and Zep. These cover common use cases. However, for production multi-agent systems that require elastic vector storage, strong write consistency, and cost-efficient scaling to billions of vectors, a custom provider backed by Amazon S3 Vectors is the right fit.
Why Amazon S3 Vectors as the persistent memory backend
Building persistent memory for multi-agent AI systems with Amazon S3 Vectors covers the architectural rationale in depth. The following table summarizes the properties that make S3 Vectors the right fit for NAT’s memory layer:
| Requirement | S3 Vectors capability |
| Semantic retrieval | Vector similarity search with configurable distance metrics (cosine, euclidean) |
| Scoped queries | Filterable metadata on each vector (strings, numbers, Booleans, lists) |
| Multi-agent coordination | Strong write consistency. Memories are visible immediately after insertion |
| Scale | Up to 2 billion vectors per index with no capacity planning |
| Cost efficiency | Pay only for storage, writes, and queries with no idle compute |
| Access control | AWS Identity and Access Management (IAM) policies per bucket and index. Per-tenant indexes for hard isolation |
Prerequisites
To follow along with the implementation in this post, you need:
- An AWS account with permissions to create Amazon S3 Vectors resources and Amazon EKS clusters.
- An existing Amazon EKS cluster (see Getting started with Amazon EKS).
- NVIDIA NeMo Agent Toolkit installed (tested with version 1.6).
- Python 3.11 or 3.12 (NAT requires >=3.11, <3.14).
- An embedding model for generating vector representations (this post uses Amazon Titan Text Embeddings V2).
- kubectl and Docker for container and cluster operations.
Implementing S3 Vectors as a NAT memory provider
The implementation has three steps:
Step 1: Create the S3 Vectors infrastructure
Step 2: Implement a custom MemoryEditor plugin
Step 3: Configure the agent workflow
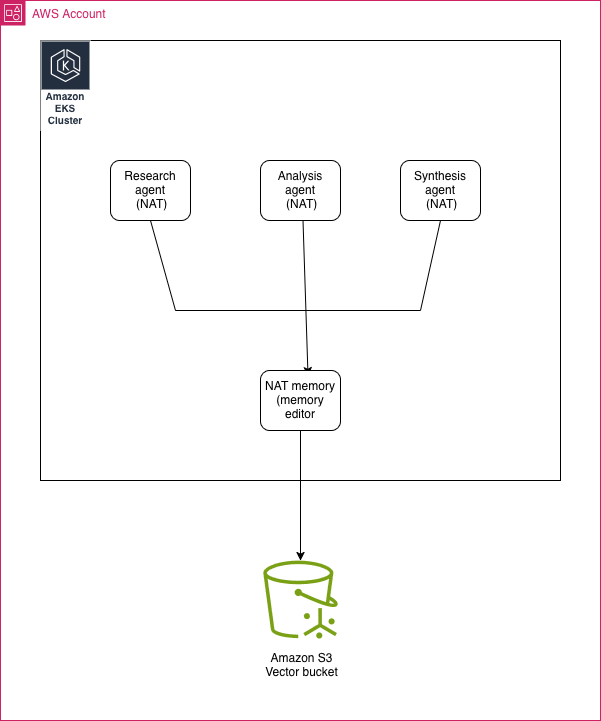
Figure 1: The three steps to implement Amazon S3 Vectors as a NAT memory provider
Step 1. Create the Amazon S3 Vectors infrastructure
The following code creates a vector bucket and an index with a metadata schema designed for agent memory. The index uses 1024 dimensions to match the output of Amazon Titan Text Embeddings V2, and it marks the large content field as non-filterable metadata:
import boto3

REGION = "us-west-2"
VECTOR_BUCKET = "amzn-s3-demo-research-agent-memory"
INDEX_NAME = "agent-long-term-memory"

s3vectors = boto3.client("s3vectors", region_name=REGION)

# Create the vector bucket
s3vectors.create_vector_bucket(vectorBucketName=VECTOR_BUCKET)

# Create the index (1024 dimensions matches Amazon Titan Text Embeddings V2)
s3vectors.create_index(
    vectorBucketName=VECTOR_BUCKET,
    indexName=INDEX_NAME,
    dataType="float32",
    dimension=1024,
    distanceMetric="cosine",
    metadataConfiguration={"nonFilterableMetadataKeys": ["content"]},
)
After creating the bucket and index, you can implement the memory provider that reads from and writes to them.
Step 2. Implement a custom MemoryEditor plugin
The following code implements the MemoryEditor interface as an Amazon S3 Vectors backend and registers it so that NAT can discover it:
import boto3
import json
import uuid
from datetime import datetime, timezone
from nat.plugin_api import MemoryBaseConfig, MemoryEditor, MemoryItem, register_memory
from nat.builder.builder import Builder


class S3VectorsMemoryConfig(MemoryBaseConfig, name="s3vectors_memory"):
    """NAT memory provider configuration for Amazon S3 Vectors."""
    vector_bucket: str
    index_name: str
    aws_region: str = "us-west-2"
    default_top_k: int = 5


class S3VectorsMemoryEditor(MemoryEditor):
    """NAT MemoryEditor backed by Amazon S3 Vectors."""

    def __init__(self, config: S3VectorsMemoryConfig):
        self._vector_bucket = config.vector_bucket
        self._index_name = config.index_name
        self._default_top_k = config.default_top_k
        self._s3vectors = boto3.client('s3vectors', region_name=config.aws_region)
        self._bedrock = boto3.client('bedrock-runtime', region_name=config.aws_region)

    def _get_embedding(self, text: str) -> list[float]:
        """Generate embeddings using Amazon Titan Text Embeddings V2."""
        response = self._bedrock.invoke_model(
            modelId='amazon.titan-embed-text-v2:0',
            contentType='application/json',
            accept='application/json',
            body=json.dumps({
                'inputText': text,
                'dimensions': 1024,
                'normalize': True
            })
        )
        return json.loads(response['body'].read())['embedding']

    async def add_items(self, items: list[MemoryItem], **kwargs) -> None:
        """Store memory items as vectors in Amazon S3 Vectors."""
        vectors = []
        for item in items:
            # Build the text to embed from the memory content
            text = item.memory or json.dumps(item.conversation)
            embedding = self._get_embedding(text)
            # Use uuid4 to prevent key collisions within the same second
            key = f"mem_{item.user_id}_{uuid.uuid4().hex[:12]}"
            # Note: S3 Vectors metadata values have size limits.
            # Truncate content to 1024 characters for production use.
            content_for_metadata = text[:1024]
            mem_metadata = {
                'user_id': item.user_id,
                'memory_type': item.metadata.get('memory_type', 'episodic'),
                'agent_id': item.metadata.get('agent_id', ''),
                'team_id': item.metadata.get('team_id', ''),
                'task_id': item.metadata.get('task_id', ''),
                'confidence': item.metadata.get('confidence', 0.8),
                'created_at_epoch': int(datetime.now(timezone.utc).timestamp()),
                'is_shared': item.metadata.get('is_shared', True),
                'source': item.metadata.get('source', 'agent'),
                'content': content_for_metadata,
            }
            # Add domain-specific metadata if present
            if 'ticker' in item.metadata:
                mem_metadata['ticker'] = item.metadata['ticker']
            vectors.append({
                'key': key,
                'data': {'float32': embedding},
                'metadata': mem_metadata
            })
        self._s3vectors.put_vectors(
            vectorBucketName=self._vector_bucket,
            indexName=self._index_name,
            vectors=vectors
        )

    async def search(self, query: str, top_k: int = None, **kwargs) -> list[MemoryItem]:
        """Retrieve semantically relevant memories from Amazon S3 Vectors."""
        query_embedding = self._get_embedding(query)
        effective_top_k = top_k or self._default_top_k
        # Build metadata filter from kwargs
        filter_expr = {}
        for field in ('agent_id', 'memory_type', 'ticker', 'team_id', 'user_id'):
            if field in kwargs:
                filter_expr[field] = {'$eq': kwargs[field]}
        # Support boolean filter for is_shared
        if 'is_shared' in kwargs:
            filter_expr['is_shared'] = {'$eq': kwargs['is_shared']}
        response = self._s3vectors.query_vectors(
            vectorBucketName=self._vector_bucket,
            indexName=self._index_name,
            queryVector={'float32': query_embedding},
            topK=effective_top_k,
            filter=filter_expr if filter_expr else None,
            returnMetadata=True
        )
        results = []
        for vec in response.get('vectors', []):
            results.append(MemoryItem(
                conversation=[],
                tags=[vec['metadata'].get('memory_type', '')],
                metadata=vec['metadata'],
                user_id=vec['metadata'].get('user_id', ''),
                memory=vec['metadata'].get('content', '')
            ))
        return results

    async def remove_items(self, **kwargs) -> None:
        """Remove memory items from Amazon S3 Vectors."""
        keys = kwargs.get('keys', [])
        if keys:
            self._s3vectors.delete_vectors(
                vectorBucketName=self._vector_bucket,
                indexName=self._index_name,
                keys=keys
            )


# Register the memory provider so NAT can discover it
@register_memory(config_type=S3VectorsMemoryConfig)
async def build_s3vectors_memory(config: S3VectorsMemoryConfig, builder: Builder):
    yield S3VectorsMemoryEditor(config)
The plugin generates embeddings with Amazon Titan Text Embeddings V2, stores each memory as a vector with scoped metadata, and translates search filters into Amazon S3 Vectors metadata queries.
Step 3. Configure the NAT agent workflow
With the plugin defined, configure it in NAT’s YAML config and wire it into an agent workflow:
# config.yml - NAT agent configuration with Amazon S3 Vectors memory
memory:
  agent_memory:
    _type: s3vectors_memory
    vector_bucket: "amzn-s3-demo-research-agent-memory"
    index_name: "agent-long-term-memory"
    aws_region: "us-west-2"

functions:
  add_memory:
    _type: add_memory
    memory: agent_memory
    description: |
      Store important findings, patterns, or facts to long-term memory.
      Use this after discovering new information during research.
  get_memory:
    _type: get_memory
    memory: agent_memory
    description: |
      Retrieve relevant prior knowledge before starting research.
      Query with the current research topic to recall related findings.
  web_search:
    _type: web_search
  financial_data:
    _type: financial_data_api

workflow:
  _type: auto_memory_agent
  inner_agent_name: research_agent
  memory_name: agent_memory
  llm_name: bedrock_llm
  save_user_messages_to_memory: true
  retrieve_memory_for_every_response: true
  save_ai_messages_to_memory: true

llm:
  bedrock_llm:
    _type: bedrock
    model_id: "anthropic.claude-sonnet-4-20250514"
    temperature: 0.3
With the auto_memory_agent wrapper, you can capture and retrieve memory automatically. User messages and agent responses are stored, and relevant context is injected before each agent call. This design removes the need for the LLM to explicitly invoke memory tools.
Responsible AI and data handling considerations
Because this solution persists conversation history and user memory, plan for how that data is retained and accessed. Set a retention policy for stored memories, and use the memory consolidation and removal paths in this post to expire data you no longer need. Avoid storing personally identifiable information (PII) in memory metadata, and redact or tokenize sensitive fields before you embed them. Scope access with per-tenant indexes and least-privilege IAM policies so that each agent reads and writes only the memory it owns.
Putting Amazon S3 Vectors in practice: Multi-agent investment research
The following use case demonstrates this pattern in practice. Consider three specialized agents collaborating on an investment research tool:
- Research Agent – Gathers market data, earnings reports, and news.
- Analysis Agent – Performs quantitative analysis and identifies patterns.
- Synthesis Agent – Produces reports combining findings from both agents.
With persistent memory, each agent builds on prior work. The Research Agent recalls previously collected data, avoiding redundant API calls. The Analysis Agent builds on patterns identified in prior sessions. The Synthesis Agent accesses cumulative findings to produce progressively richer reports.
Multi-agent memory coordination
Each agent uses the same S3 Vectors index but writes with its own agent_id in the metadata. Agents retrieve shared knowledge using metadata filters:
# Analysis Agent retrieves Research Agent's shared findings
research_findings = await memory_client.search(
    query=f"Recent research findings for {ticker}",
    top_k=10,
    team_id='investment-research',
    is_shared=True
)

# Synthesis Agent queries all team knowledge
all_team_knowledge = await memory_client.search(
    query=f"Complete analysis and research for {ticker} Q2 2026",
    top_k=20,
    team_id='investment-research'
)
NAT’s built-in multi-tenant memory isolation uses user_id to scope memory per user. For multi-agent team coordination, the team_id metadata field provides an additional grouping dimension within the same S3 Vectors index.
Memory consolidation
Over time, episodic memories accumulate. Periodically consolidating them into semantic memories (generalized knowledge) keeps retrieval precise and efficient. You can trigger consolidation through a scheduled cron job, a vector count threshold, or an agent-initiated signal after a configurable number of research cycles:
async def consolidate_memories(ticker: str, memory_client, workflow):
    """Distill episodic memories into durable semantic knowledge."""
    episodes = await memory_client.search(
        query=f"All findings about {ticker}",
        top_k=5