Disaster recovery (DR) at scale is hard. When thousands of microservices span multiple AWS Regions, coordinating a reliable failover becomes a major operational challenge. At Intuit, we operate at this scale. We support products that millions of people rely on to run their businesses and manage their finances. These include TurboTax, QuickBooks, Mailchimp, and Credit Karma. To close that gap, we built an agentic disaster recovery assistant with Amazon Bedrock. It builds on our existing centralized internal disaster recovery system called Ecosystem Wide Orchestrator Kit (EWOK). EWOK standardizes failover execution across compute, databases, networking, caches, and asynchronous workloads. Service owners declare recovery intent in YAML, and the EWOK system orchestrates the underlying infrastructure actions, reducing recovery times from several hours to about 20 minutes for supported workloads.
EWOK solved execution but not decision-making. Choosing which recovery workflow applies, and confirming an asset is ready, still relied on the tribal knowledge of experienced on-call engineers, as did handling the exceptions that surface mid-recovery. A common example arises during a change-freeze window. This is a period when deployments and changes are tightly restricted to protect service availability during critical business times such as tax season. If a failover request lands during one of these windows, it gets rejected. The engineer must know the detailed emergency-override procedure to proceed.
To close this gap, we built EWOK Agent, an AI-powered agent built with Amazon Bedrock. Teams across Intuit have used it to run failovers for the past eight months. Amazon Bedrock gives us access to hundreds of foundation models from leading AI providers through a single API. We can evaluate and select the right model for failover reasoning, and switch models as our needs evolve, without rearchitecting the agent. It also provides built-in Amazon Bedrock Guardrails, along with security and privacy protections. Our data isn’t used to train models and remains encrypted in transit and at rest. This matters when the agent operates on production financial systems. Because Amazon Bedrock is fully managed, we added this reasoning layer on top of EWOK without provisioning or managing model infrastructure ourselves. We deliver EWOK Agent as a plugin. Engineers can install it and run failovers directly from Intuit’s Engineering portal or integrated development environment (IDE) of their choice.
In this post, we explain the architecture and design decisions behind the EWOK Agent. We cover the design principles for encoding failover knowledge as skills. We describe how a thin Amazon Bedrock layer connects foundation models to those skills. We show how an agentic loop turns a plain-language request like “failover payments-gateway in production” into a validated, policy-aligned recovery execution. We focus on the design patterns rather than a step-by-step implementation.
Throughout, we hold one idea firmly. The model decides what to do, and the EWOK Agent deterministically executes how. Each design choice described in the following sections exists to keep that boundary crisp.
Before you begin
This post describes an architecture and a reusable pattern rather than a step-by-step deployment. The code samples are illustrative excerpts, not a complete, runnable implementation. To follow the design decisions and adapt the pattern to your own environment, it helps to have:
- Familiarity with Amazon Bedrock and how model access is granted for a foundation model (FM) in your AWS Region. Amazon Bedrock foundation model availability varies by AWS Region, so check that your chosen model is available in your Region before adopting this pattern.
- Familiarity with the Amazon Bedrock Converse API and its tool use (function calling) capability, which the skill-to-tool compilation relies on.
- An understanding of Amazon Bedrock Guardrails and the IAM actions a Bedrock workload typically calls (for example,
bedrock:Converse,bedrock:ConverseStream,bedrock:InvokeModel, andbedrock:ApplyGuardrail), so the security and execution-boundary decisions are straightforward to follow. - Familiarity with Python and the AWS SDK for Python (Boto3) and langchain-aws libraries, which the illustrative code samples use.
The recovery execution layer (EWOK) is an internal Intuit system. The pattern itself (typed skills, a thin Amazon Bedrock layer, and a bounded agentic loop over a deterministic executor) is not specific to EWOK and can be applied to other systems that expose authenticated, auditable APIs.
Ecosystem Wide Orchestrator Kit (EWOK) in brief
The opening introduced EWOK as the service underneath the EWOK Agent. A few of its terms recur throughout this post, so we define them here before the walkthrough uses them.
Asset: An asset is a registered, recoverable unit, a service or serverless app, that EWOK manages traffic for. A recoverable unit typically includes:
- The compute layer (for example, a Kubernetes namespace or cluster, or an Amazon Elastic Compute Cloud (Amazon EC2) target group).
- The traffic endpoints (for example, Amazon API Gateway routes or service mesh hostnames).
- Associated databases (for example, an Amazon Aurora global database).
- Associated caches (for example, Amazon ElastiCache).
- Asynchronous or stateful dependencies (for example, message queues or pipelines).
Recovery workflow: A recovery workflow is the ordered sequence of automated steps EWOK executes to move an asset from a degraded primary region to a healthy secondary region. In other words, it is the failover. Users declare their recovery intent in a YAML configuration file that defines the workflow stages, and each stage maps to a specific action. The YAML abstracts away the mechanics, so owners focus on what to recover and in what order, not low-level infrastructure details.
Asset: payments-gateway
primary: region-a
secondary: region-b
stages:
  - compute # scale up capacity in the secondary region
  - database # promote the secondary replica to primary
  - cache # warm and cut over the cache tier
  - traffic # shift routing from primary to secondary
Readiness check: A readiness check is a pre-flight validation that runs against an asset before a failover workflow is allowed to execute. It verifies that the asset meets EWOK’s requirements for safely orchestrating a traffic move.
Policy gates: Policy gates are guardrails or restrictions that EWOK evaluates before or during workflow execution to determine whether a workflow is permitted to proceed. They represent organizational, operational, or compliance-level controls that sit above the technical readiness of the asset itself.
Execution ID: An execution ID is a unique value assigned to a single run of an EWOK workflow. It identifies that specific execution instance end to end, from the moment the workflow is triggered through all its stages to completion or failure.
Change record: A formal entry in the change-management system that authorizes and documents a production change. EWOK opens one when a production workflow starts and closes it when the run ends, so every failover is authorized and auditable through the same process a human operator would follow, and no production workflow runs without one.
How teams run failover
Before diving into the architecture, the following demonstrates an engineer’s experience running a failover with EWOK using EWOK Agent.
An on-call engineer, working from our internal engineering portal or an IDE, tells the agent:
“Failover payments-gateway in production”
EWOK Agent then:
- Resolves the asset and discovers its available recovery workflows.
- Selects the appropriate failover workflow (or asks the engineer to choose when several apply).
- Validates readiness and checks policy gates, such as an active change-freeze window.
- Triggers execution through the EWOK system and returns the execution ID and change record.
- Monitors and reports stage-by-stage status until the failover completes.
Those tasks used to be a sequence of runbook lookups and console visits. Earlier, an engineer coordinated the API calls. Now they supervise conversations. The engineer stays in the loop for judgment calls and approvals but no longer needs to be the orchestrator.
Solution overview
At a high level, the EWOK Agent consists of four layers. The following diagram illustrates the end-to-end flow, from an engineer’s request to a deterministic recovery action. The architecture is organized top to bottom:
- Consumer layer (top): holds Intuit’s Engineering Portal and IDE integration, connected through Model Context Protocol (MCP), the two entry points where an engineer submits a plain-language request.
- Agent layer: runs on Amazon Bedrock and pairs foundation model selection and a bounded reasoning loop with Amazon Bedrock Guardrails that are applied on every invocation. It handles model selection, guardrails, and skill dispatch.
- Skill layer (right): holds typed, versioned skills, each defined as a YAML schema plus a prompt body, which compiles to tool specifications that the model selects from.
- Execution layer (bottom): is the EWOK API layer, which deterministically performs asset resolution, recovery workflow lookup, readiness checks, policy gates,
execution-ID-basedtracking, change records, and the failover itself, through workload-specific agents for compute, database, cache, and traffic.
Status flows back up the same path, from the execution layer through the agent layer to the engineer.
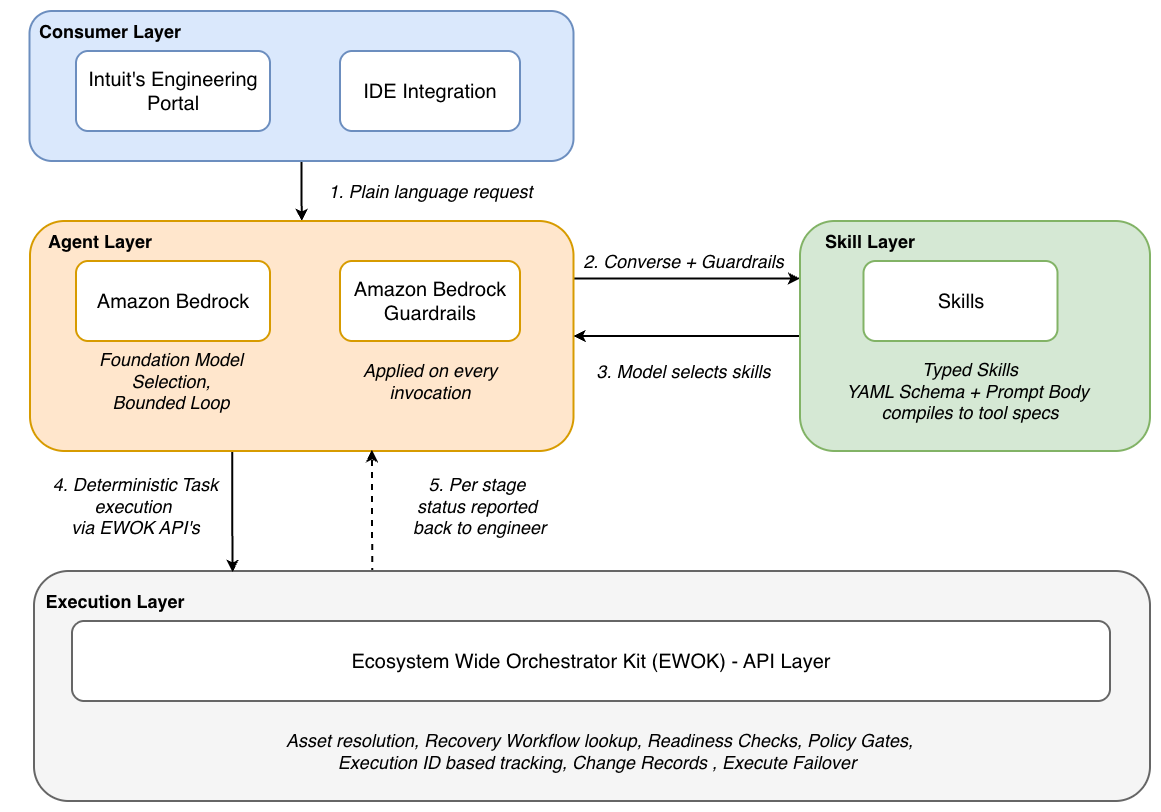
Figure 1: EWOK Agent architecture and request flow, from an engineer’s request through Amazon Bedrock to a deterministic recovery action in EWOK
- An on-call engineer issues a plain-language request from the internal engineering portal or an IDE assistant (through MCP).
- The agent layer sends the request, together with the compiled skill tool specifications, to a foundation model through the Amazon Bedrock Converse API, with an Amazon Bedrock Guardrail attached to each invocation.
- The model selects the appropriate skill and returns a structured tool-use request (for example, the failover skill with the target asset and environment).
- The skill’s executor runs the selected operation against EWOK’s APIs, resolving the asset, checking policy gates, creating a change record, and invoking the workflow, then returns a structured result.
- EWOK executes the approved recovery workflow through workload-specific agents across the compute, database, cache, and traffic tiers, and reports stage-by-stage status back through the loop to the engineer.
Encoding failover knowledge as skills
The foundational design decision behind EWOK Agent was to stop writing runbooks for humans and start writing skills, definitions that are simultaneously human-readable procedure and machine-consumable capability.
A skill is a Markdown file with two parts:
- YAML frontmatter declaring a typed I/O schema, which serves as the operational contract.
- A prompt body containing the instructions, rules, and decision logic the model follows.
Here is a simplified skill definition for failover management:
name: failover-manager
description: >
  Manages failover workflows for assets: list workflows, invoke
  failover, and check execution status. Use when the user asks to
  "trigger failover" or "check failover status" for an asset.
input_schema:
  operation:
    type: string
    description: "'get-workflows', 'invoke-failover', or 'get-status'"
    required: true
  asset_name:
    type: string
    description: "Name or alias of the asset to act on"
    required: true
  environment:
    type: string
    description: "Target environment, e.g. 'staging' or 'production'"
    required: true
  incident_number:
    type: string
    description: "Only needed to override an active change-freeze window"
    required: false
output_schema:
  status:
    type: string
    description: "'success' or 'error'"
  result:
    type: object
    description: "Operation-specific payload (workflows, execution ID, or status)"
The schema does more than documenting the skill. It compiles directly into the tool definition the model reasons against. The skill’s actions then run through a real executor against EWOK’s APIs.
How we write skill prompt bodies
The prompt body is where operational judgment lives. We hold it to a structured, rule-based format rather than free-form prose:
- Explicit operation walkthroughs: Numbered steps per operation, each mapping to exactly one executor call.
- Strict stop-on-error rules: A failed step ends the skill immediately, and the model is explicitly forbidden from retrying or improvising alternatives, because the executor already handles transient retries.
- Policy gates as first-class branches: These are defined flows with defined exits, not errors.
- A structured response contract: The model populates the declared output schema. It does not invent its own.
The policy-gate pattern is best shown by example. At Intuit, failovers during a change-freeze window are blocked unless tied to an incident. That judgment call used to live in an engineer’s memory of the change policy. Now it is an explicit branch in the skill body:
If the invoke result has status "change_blocked":
    This is NOT an error. Change restrictions are active for this asset.
    Ask the user for ONE of:
    - an incident number (e.g. INC0001234), or
    - an emergency justification (24-100 characters)
    Re-run the invoke exactly once with the value provided.
    If the user declines, stop and report that the failover was not executed.
The Amazon Bedrock layer: Plugging models into skills
Skills are deliberately foundation model agnostic. A thin Amazon Bedrock layer connects them to a foundation model, and it does three jobs.
- The first job is to compile each skill’s schema into an Amazon Bedrock tool specification. The Amazon Bedrock Converse API accepts a
toolConfigdescribing the tools a model may call. The loader runs the following function once per skill. At load time, each skill becomes one tool entry:
def to_tool_spec(skill) -> dict:
    """Compile a skill's declared schema into a Bedrock toolSpec."""
    properties = {
        name: {"type": field.type, "description": field.description}
        for name, field in skill.input_schema.items()
    }
    required = [n for n, f in skill.input_schema.items() if f.required]
    return {
        "toolSpec": {
            "name": skill.name,
            "description": skill.description,
            "inputSchema": {"json": {
                "type": "object",
                "properties": properties,
                "required": required,
            }},
        }
    }
This is what lets the model choose the right capability from context. The request “failover payments-gateway in production” activates the failover skill with operation=invoke-failover, asset_name=payments-gateway, and environment=production, without us hardcoding a decision tree.
- The second job is to keep the model pluggable. Because the Amazon Bedrock Converse API is uniform across models, the model is a configuration value rather than an architectural commitment. We evaluate and adopt newer foundation models by changing configs, and the skills, the loop, and the executors stay untouched.
- The third job is to attach guardrails. We attach an Amazon Bedrock Guardrail to ev