As organizations move from single-purpose agents to multi-agent systems, the infrastructure requirements change. A lone agent handling customer queries can run in a serverless environment with short-lived sessions. But when you need three agents collaborating on a creative workflow that spans several days, sharing context and building on each other’s output, serverless sessions that cap at a few hours don’t cut it.
In this post, we walk through deploying a music production pipeline: One agent runs a generative audio model on the instance’s own GPU. The other two open the .wav file it wrote, off a shared volume. By the end, you will have a track you can play. You will also have learned how to create capacity providers, deploy agents from different artifact types, orchestrate agent-to-agent collaboration using shared sessions, and persist workflows across multiple days.
Amazon Bedrock AgentCore offers two compute options for hosting agents. MicroVMs are the serverless option: fast cold starts, session isolation, and consumption-based pricing. Runtime Instances are the new option: AWS managed EC2 infrastructure for persistent, long-running agent workflows. Both use the same runtime APIs, but Instances add multi-day sessions, GPUs, persistent volumes, and the ability to colocate multiple agents on a single instance.
How Runtime Instances differs from MicroVM
Both options support custom frameworks (CrewAI, LangGraph, LlamaIndex, Strands Agents), work with your choice of foundation model, integrate with MCP and A2A, and share the same AgentCore runtime APIs. The difference is in the underlying compute model.
| Capability | MicroVM (Serverless) | Runtime Instances |
| Compute | Fully AWS managed | AWS managed EC2 instances |
| Session duration | Up to 8 hours | Up to 14 days |
| Agents per compute | One runtime (microVM) hosts one agent (1:1) | One instance (EC2) can host multiple agents (1:N) |
| Artifact types | Container image and Amazon S3 source | Container image and Amazon S3 source |
| GPU access | Not supported | Yes, on a supported instance family |
| Session persistence | Session-scoped | Persistent storage (Amazon EBS) |
| Pricing | Consumption-based | EC2 instances run in your account. Use your AWS Savings Plans and On-Demand Capacity Reservations (ODCRs) |
| Scaling | Scale on demand | Managed by capacity provider |
An agent is a workload running within a session. Unlike the MicroVM model, where one runtime hosts one agent, a single Instances session can host multiple agents. When two agent runtimes share the same capacity provider, you can invoke them with the same runtimeSessionId to land both agents on the same EC2 instance. There, they share a filesystem and can collaborate on the same task.
Solution overview
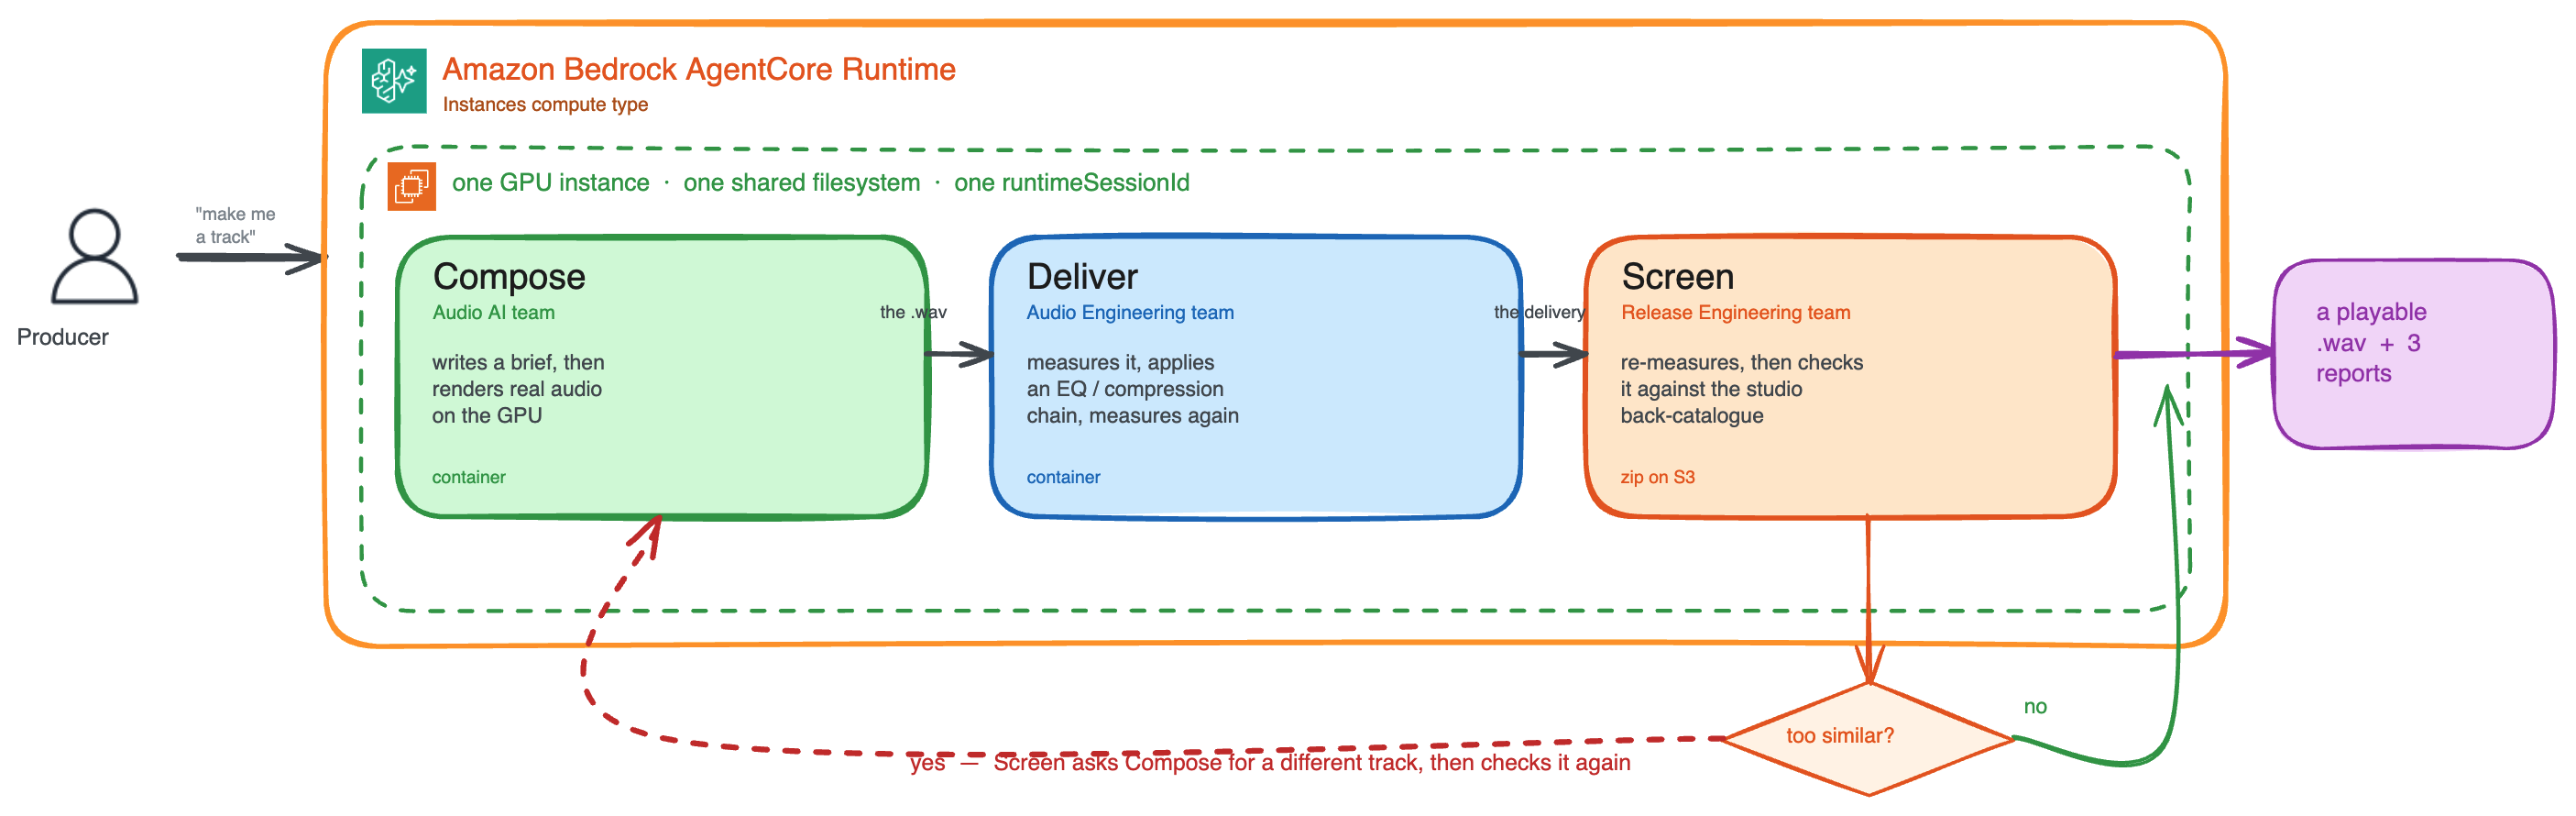
Figure 1: The three-agent pipeline (Compose, Deliver, Screen) sharing one GPU instance and session
We will build a music production system that uses three specialized agents:
- Composition agent (Audio AI team): Turns a producer’s request into a musical brief using Claude Sonnet 4.6, then renders the actual audio with a generative music model (ACE-Step, an open-source foundation model (FM) for music generation), running on the instance’s own GPU. Packaged as a container image in Amazon Elastic Container Registry (Amazon ECR).
- Delivery agent (Audio Engineering team): Reads the rendered track off the shared filesystem and measures it, then asks Claude Sonnet 4.6 for a delivery chain (EQ, compression, limiting) based on those measurements rather than on the audio itself. Real signal processing applies to the chain, and the result is measured again to confirm it hit the delivery target. Packaged as a container image in Amazon ECR.
- Compliance agent (Release Engineering team): Independently re-measures the finished delivery, checks it against the delivery targets the delivery agent claimed, and screens it for harmonic similarity against the studio’s own back catalog. If the screen objects, the agent calls back to the composition agent for a replacement and re-screens. Delivered as a zip file on Amazon Simple Storage Service (Amazon S3).
The workflow: a producer starts a track. The composition agent writes a brief and renders real audio on the instance’s GPU. The delivery agent opens that file, measures it, applies a chain it derived from those measurements, and measures again to prove the result landed on target. The compliance agent then re-measures independently, checks the delivery targets, and screens the audio against the studio’s back catalog. If the screen flags a match, it calls back to the composition agent to generate an alternative. The producer ends up with a playable .wav and three reports explaining every decision.
What makes this possible on Runtime Instances:
- Colocation via shared session ID. Each agent has its own runtime, but by invoking them with the same
runtimeSessionIdon the same capacity provider, AgentCore places them on the same instance with the same volumes mounted. They share a filesystem and can access each other’s outputs. - A GPU you can use. The composition agent runs the ACE-Step foundation model directly on the instance’s NVIDIA L4, rendering 20 seconds of 48 kHz stereo in about 9 seconds. The model and its dependencies live on a persistent volume. Built once for a session, then reused by every invocation in it, including after an overnight stop.
- Independent deployment. Each team ships its own artifact on its own cadence. The Audio AI team pushes a new composition image without coordinating with Audio Engineering or Release Engineering, and the other two keep running untouched.
- Multi-day persistence. A producer works on composition Monday, stops the session overnight, and resumes delivery Tuesday. The instance idles automatically and resumes the next invoke.
- Mixed artifacts. Containers from ECR and code packages from S3 coexist on one capacity provider. Teams choose the packaging that fits their workflow.
Walkthrough
From here on, this post is hands-on. You will prepare your AWS account, then run a three-agent pipeline that renders, generates, and clears a finished track, producing a .wav file you can play. Work through the steps in order. You will start by confirming the prerequisites, then define the three agents (Step 1), create a capacity provider that provisions the GPU instance and its persistent volumes (Step 2), deploy each agent as its own runtime (Step 3), and invoke them with a shared session ID so they can colocate on one instance and hand work to each other (Step 4). Finally, Step 5 shows how any one team can ship a new version of its agent without disturbing the others. The complete sample is in the AgentCore samples GitHub repository.
Prerequisites
Before you begin, make sure you have:
- An AWS account, with credentials for a principal that can create infrastructure. This sample creates AWS Identity and Access Management (IAM) roles, an S3 bucket, ECR repositories, and an AgentCore capacity provider and runtimes.
- AWS Command Line Interface (AWS CLI) installed and configured.
- A virtual private cloud (VPC) with at least one subnet and security group.
- Model access enabled in the Amazon Bedrock console for Anthropic Claude Sonnet 4.6.
- Finch or another OCI-compatible container tool installed locally.
- Python 3.10+ installed.
- boto3 ≥ 1.36.0 or botocore ≥ 1.43.72. Older versions lack
create_capacity_provider, anddeploy.pywill fail.
For the complete working code, see the AgentCore samples repository on GitHub.
Step 1: Define your agents
AgentCore Runtime Instances supports any agent framework. In this sample, each agent is a Python application built with Strands Agents.
Two details are commonly misconfigured, and both fail confusingly:
@app.entrypoint
def invoke(payload, context):  # the parameter must be NAMED "context"
    session_id = getattr(context, "session_id", None) or "local-session"
The SDK dispatches on the parameter name (it checks params[1] == "context"). That is the only way to read the session ID, which the agents need in order to find each other’s files and to call one another.
Second, build the Agent inside the handler, not at module scope:
def build_agent(session_id: str, track_id: str) -> Agent:
    return Agent(
        name=AGENT_NAME,
        model=BedrockModel(model_id=MODEL_ID, region_name=REGION),
        system_prompt=SYSTEM_PROMPT,
        session_manager=FileSessionManager(
            session_id=f"{session_id}-{AGENT_NAME}",
            storage_dir=str(track_path(track_id) / f".sessions-{AGENT_NAME}"),
        ),
    )
A module-level Agent is shared across concurrent requests, and Strands rejects re-entrant invocation with Agent is already processing a request. History lives on the volume through FileSessionManager, which is how a session resumed days later remembers earlier decisions.
Composition agent
The composition agent turns the producer request (prompt) into a musical brief, using Claude Sonnet 4.6, then renders the actual audio with the ACE-Step foundation model:
@app.entrypoint
def invoke(payload, context):
    session_id = getattr(context, "session_id", None) or "local-session"
    track_id = payload.get("track_id", "demo-track")
    if payload.get("mode") == "prepare":
        return {"status": "ok", "model_stack": prepare_model_stack()}
    ensure_track_dir(track_id)
    brief = build_agent(session_id, track_id)(
        payload["prompt"], structured_output_model=CompositionBrief
    ).structured_output
    wav = track_path(track_id) / "composition.wav"
    render = render_audio(wav, brief, duration_s=payload.get("duration_s", 30.0))
    write_text(track_id, "composition.md", brief.to_markdown(render))
    return {"status": "ok", "render": render, "host": host_info(),
            "artifacts": [publish(track_id, wav)]}
The mode=prepare call builds the stack onto the volume, a virtualenv with CUDA PyTorch and ACE-Step. The render runs as a subprocess under that volume’s interpreter:
proc = subprocess.run(
    [status["python"], status["runner"], "--out", str(out_path),
     "--prompt", brief.style_tags, "--duration", str(duration_s)],
    capture_output=True, text=True, check=False,
    timeout=RENDER_TIMEOUT_S, env=gpu_env(),
)
Delivery agent
The delivery agent reads the rendered track off the shared filesystem and measures it. It uses Claude Sonnet 4.6 to choose EQ bands, compressor settings, and what to leave alone. The digital signal processing (DSP) is then applied. Then the output is measured again, so the plan is checked rather than trusted.
before = audio.measure(str(source))  # ITU-R BS.1770-4
plan = build_agent(session_id, track_id)(
    f"Prepare this for {platform} delivery.\n{json.dumps(before.to_dict())}",
    structured_output_model=DeliveryPlan,
).structured_output
data, rate = audio.read_audio(str(source))
bands = [b.model_dump() for b in plan.eq_bands]
if bands:
    data = audio.apply_filters(data, rate, bands)
if plan.compressor.enabled:
    data, _ = audio.compress(
        data, rate,
        threshold_db=plan.compressor.threshold_db,
        ratio=plan.compressor.ratio,
        attack_ms=plan.compressor.attack_ms,
        release_ms=plan.compressor.release_ms,
        knee_db=plan.compressor.knee_db,
    )
data, _ = audio.normalise_loudness(data, rate, plan.target_lufs)
data, _ = audio.limit(data, rate, ceiling_dbtp=plan.target_true_peak_dbtp)
audio.write_audio(str(delivery), data, rate, subtype="PCM_24")
after = audio.measure(str(delivery))  # verify, don't trust
Compliance agent
The compliance agent independently re-measures the finished delivery, checks it against the delivery targets the delivery agent claimed, and screens it for harmonic similarity against the studio’s own back catalog. When it finds a similarity, it raises a flag and calls back to the composition agent for remediation.
client = boto3.client(
    "bedrock-agentcore", region_name=REGION,
    config=Config(read_timeout=600, retries={"max_attempts": 3, "mode": "standard"}),
)
response = client.invoke_agent_runtime(
    agentRuntimeArn=COMPOSITION_RUNTIME_ARN,  # injected at deploy time, not hard-coded
    qualifier=COMPOSITION_QUALIFIER,
    runtimeSessionId=session_id,  # the caller's own --- routes to this instance
    payload=json.dumps({
        "mode": "remediate", "track_id": track_id,
        "issue": issue,
        "avoid": avoid or {},
    }).encode(),
)
body = json.loads(response["response"].read())  # "response", not "body"
Step 2: Create a capacity provider
A capacity provider tells AgentCore what compute infrastructure to provision for your agents. You specify instance types and VPC placement. AgentCore handles provisioning and lifecycle management.
You need two IAM roles, and the distinction matters:
- An operator role AgentCore assumes to provision EC2 on your behalf: launching, tagging, and terminating instances and their network interfaces. Attach the managed policy
BedrockAgentCoreRuntimeInstancesOperatorRolePolicy. - An execution role your agent process assumes at runtime to call Bedrock and S3.
CreateAgentRuntimerequires it and fails without it.
Both trust bedrock-agentcore.amazonaws.com.
Now create the capacity provider. Note that names must use underscores (hyphens are not allowed):
control = boto3.client("bedrock-agentcore-control", region_name=REGION)
resp = control.create_capacity_provider(
name="music_production_capacity",
permissionsConfiguration={"capacityProviderOperatorRoleArn": operator_arn},
computeConfiguration={
"ec2Configuration": {
"launchTemplateSource": {
"launchParameters": {
"operatingSystem": "LINUX_X86_64", "instanceRequirements": {"allowedInstanceTypes": ["g6.xlarge"]},
}
},
"vpcConfiguration": {"subnets": subnets, "securityGroups": groups},
"volumes": [
{"ebsConfiguration": {"name": "tracks", "sizeGiB": 20,
"volumeType": "gp3", "encrypted": True}},
{"ebsConfiguration": {"name": "models", "sizeGiB": 60,
"volumeType": "gp3", "encrypted": True,
"throughput": 500}},
],
"rootVolume": {"freeSpaceGiB": 30, "volumeType": "gp3"},
"lifecycleConfiguration": {"idleInstanceTimeout": 600,
"maxLifetime": 86400},
}
},
) GPU capacity. If you hit
InsufficientInstanceCapacity across multiple Availability Zones (AZs) trying to allocate a GPU instance, you can switch to another GPU instance type, like g5.xlarge. Update allowedInstanceTypes accordingly.
Step 3: Deploy agent runtimes
Each agent here gets its own runtime. The runtimes are brought together at invoke time. When two runtimes share a capacity provider and you invoke them with the same runtimeSessionId, AgentCore places both agents on the same EC2 instance, where they share a filesystem and can collaborate on the same task. That’s how the delivery agent reads the .wav the composition agent wrote.
Next, point each runtime at the capacity provider and declare which volumes it mounts:
composition = control.create_agent_runtime(
    agentRuntimeName="music_production_composition",
    roleArn=execution_arn,  # required
    agentRuntimeArtifact={"containerConfiguration": {"containerUri": image_uri}},
    protocolConfiguration={"serverProtocol": "HTTP"},
    capacityProviderConfiguration={"capacityProviderArn": cp_arn},
    filesystemConfigurations=[
        {"capacityProviderVolume": {"volumeName": "tracks", "mountPath": "/mnt/tracks"}},
        {"capacityProviderVolume": {"volumeName": "models", "mountPath": "/mnt/models"}},
    ],
    lifecycleConfiguration={"idleRuntimeSessionTimeout": 600, "maxLifetime": 86400},
    environmentVariables={"AWS_REGION": REGION, "WORKSPACE_DIR": "/mnt/tracks",
        "MODELS_DIR": "/mnt/models", "MODEL_ID": MODEL_ID},
)
The compliance agent is the same call with a different artifact, a zip rather than an image, and only the workspace volume: