Multi-turn agents fail in ways that single-turn evaluation misses: one early mistake quietly corrupts every later turn. This post introduces the Agent Evaluation Metric (AEM), a decomposable, turn-level way to measure agent quality. We apply it to its first dimension, correctness. We show how AEM pinpoints the one turn that caused a failure and separates it from the turns that merely inherited the problem.
The correctness challenge in multi-turn agentic conversations
Evaluating agent correctness in a multi-turn conversation is hard because the property itself is fragile, and holistic scores hide where it breaks. This section shows why cascading errors defeat outcome-level evaluation and motivates a decomposable, turn-level metric.
Why correctness matters
A single wrong tool call cascades into downstream failures across turns. Consider a five-turn conversation with an enterprise assistant. The user asks to create a sales report, then refine it. In turn 2, the agent selects the right action but passes “profit” instead of “revenue.” That single error then silently propagates through every subsequent turn.
The following diagram traces that failure. It shows one early error in turn 2 cascading through turns 3–5, and how turn-level evaluation isolates the single root cause from its downstream effects.
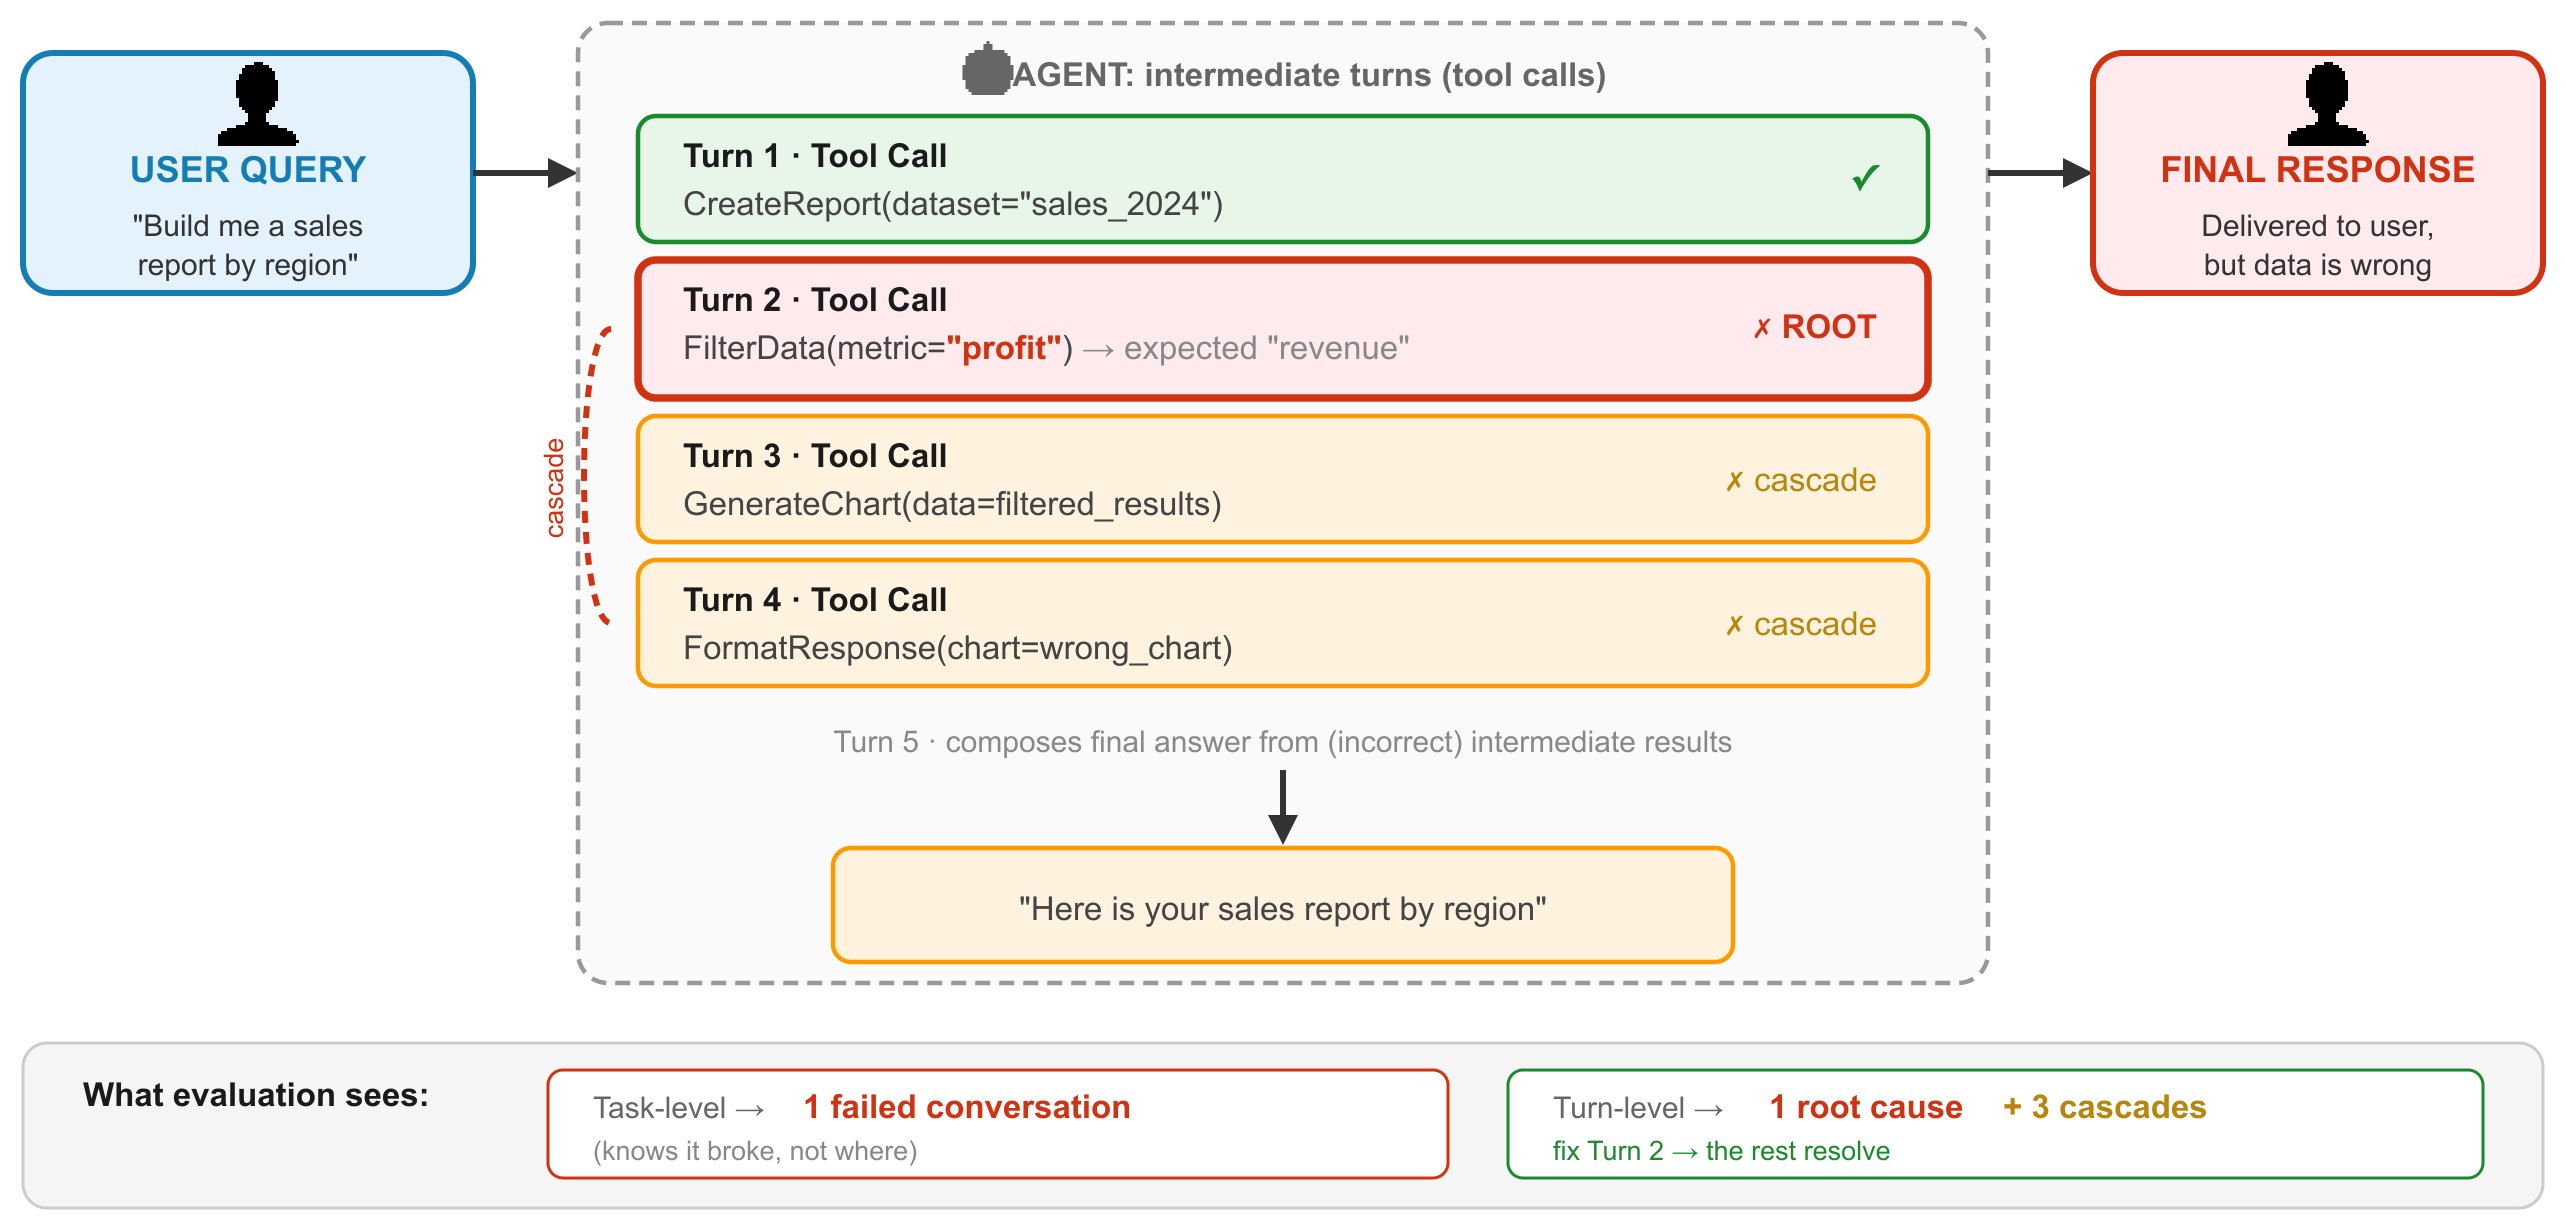
Figure 1: One early error cascades through later turns, and turn-level evaluation isolates the root cause
A task-level evaluation checks only the final outcome. It marks the entire interaction as failed without revealing that only one turn needs fixing. This is the core problem: in multi-turn agentic conversations, errors cascade, and outcome-level evaluation can’t tell root causes from their downstream effects.
Limitations of existing metrics
Most agent evaluation tools score quality holistically, at the task or response level. The current generation provides goal-completion scoring and large language model (LLM)-as-judge quality assessment. Some also add trace-level root cause analysis. These are valuable, but they share a common framing: agent quality is treated as a single signal, not broken down into parts that can be tracked independently.
What they don’t provide is a way to decompose quality into named, separately measurable sub-metrics tracked turn by turn. Knowing an agent “scored 70 percent on goal completion” doesn’t tell you whether the failures were factual errors, missing information, or wrong tool choices. A single score also can’t extend cleanly to new dimensions as requirements grow. Three gaps follow:
- Task-level metrics (goal success rate) tell you whether the agent completed the task but not which quality dimension broke down.
- Single-turn metrics (helpfulness, faithfulness) evaluate responses in isolation without considering how errors propagate across turns.
- Holistic scores cannot distinguish a factual error from a missing required field, and they offer no clear path to add new dimensions (safety, instruction retention) without re-architecting the evaluation.
A decomposable, turn-level evaluation pattern closes these gaps. It breaks quality into named sub-metrics, evaluates each turn within the full trajectory, and composes them into a single indicator. The same approach extends to new dimensions without changing the mechanism.
Correctness as a composite metric
We define agent quality as a single composite indicator built from named, separately measurable sub-metrics, computed by AEM. In this first post, AEM measures correctness through two sub-metrics:
- Truthfulness: Are the values produced by the agent factually consistent with what was expected? This applies to both parameter values in tool calls and statements in natural language responses.
- Completeness: Are all required elements present? No missing parameters, and no partial responses that omit requested information.
The following diagram shows this decomposition. It illustrates how a top-level score breaks into named sub-metrics that are measured independently and then recombined, and how the same pattern extends to future dimensions.
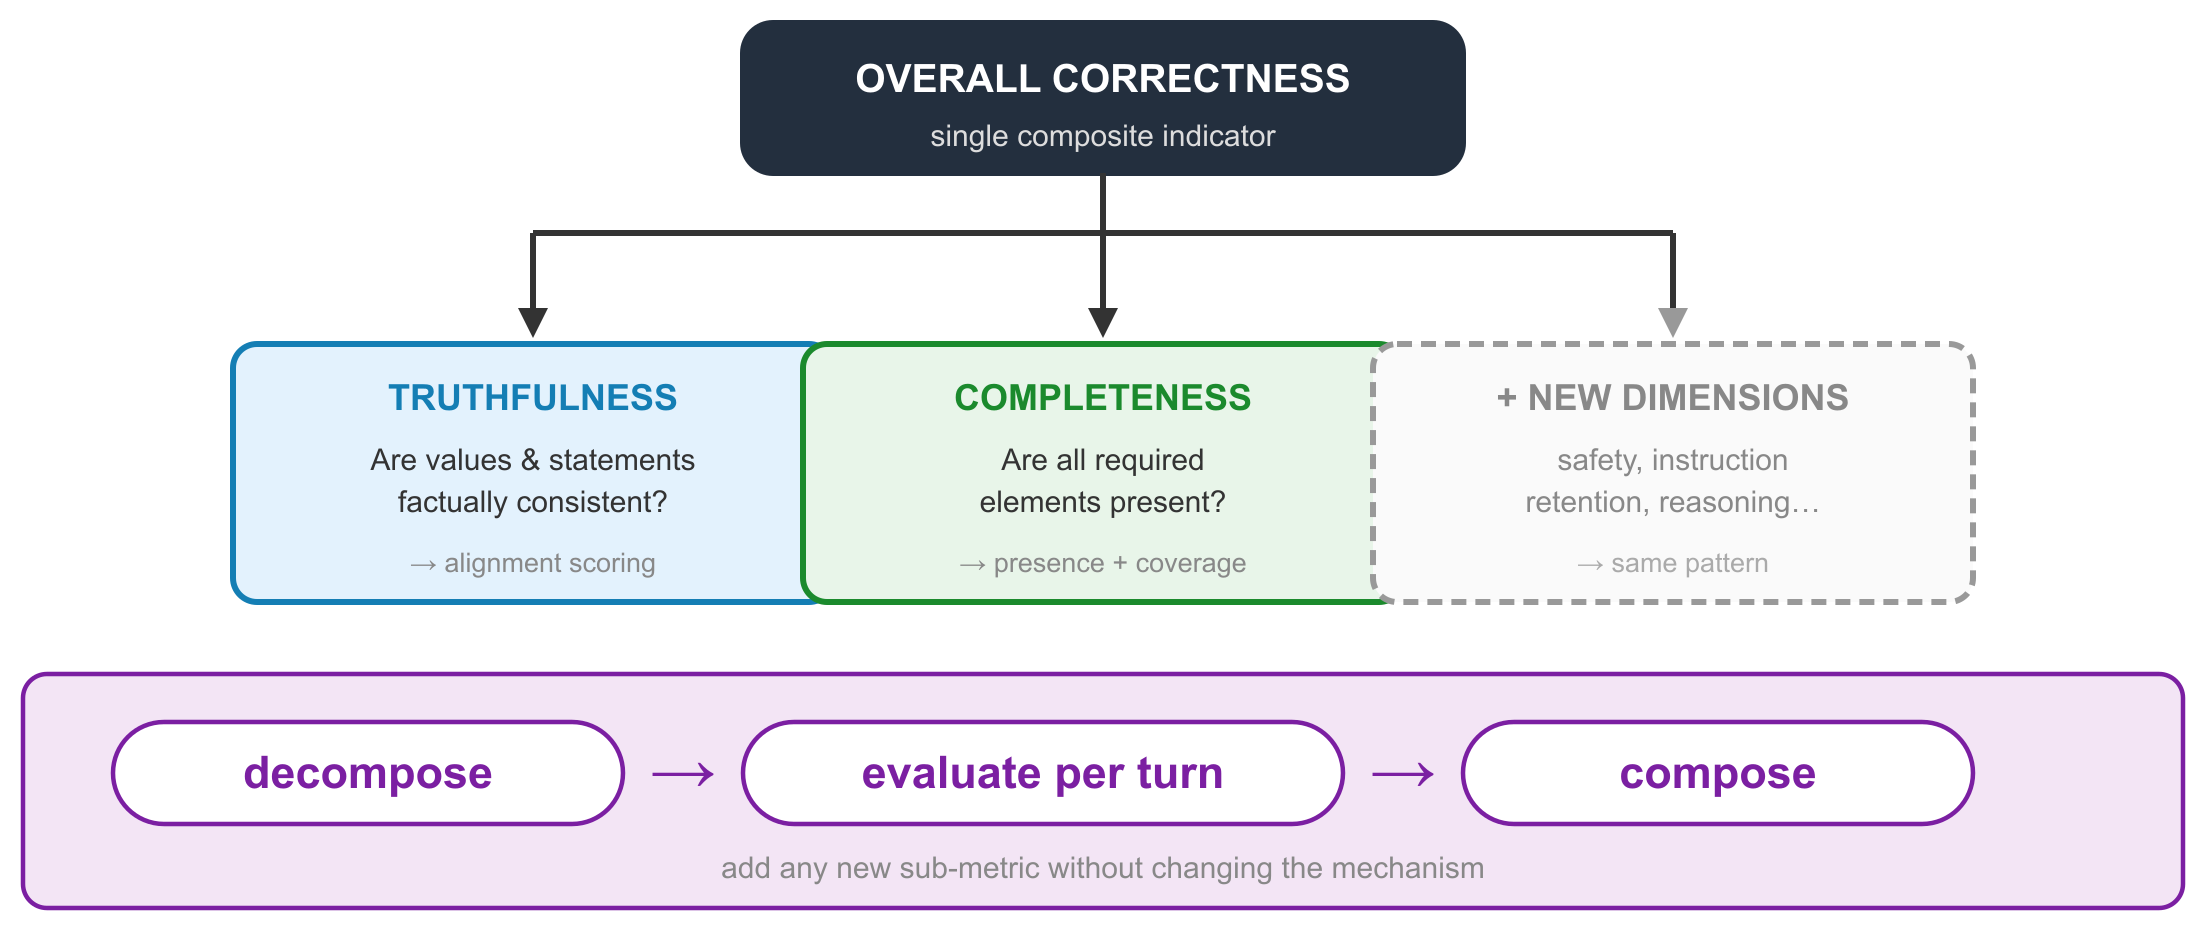
Figure 2: Correctness decomposes into named sub-metrics, extensible to new dimensions
The headline contribution is the decomposition itself. AEM isn’t a single opaque score but a composite of sub-metrics, each measurable per turn and composable across the trajectory. Tool and action selection form the structural foundation beneath them. The same decompose-evaluate-compose pattern extends to new dimensions such as safety, instruction retention, and reasoning depth. Correctness is the first dimension we instantiate.
The Agent Evaluation Metric framework
AEM turns the decomposition idea into a concrete, per-turn metric. This section defines the turn-level hierarchy, the two sub-metrics and how they compose, and the failure taxonomy that makes a score actionable.
The turn-level hierarchy
Correctness is computed per turn. A turn is either a response turn, where the agent replies to the user, or an action turn, where the agent invokes a tool. We lead with the response turn, since that is what the user ultimately sees, and the same metric applies to action turns too. Both fall under one hierarchy.
The following diagram shows that shared hierarchy. It shows the same two sub-metrics evaluating a tool call (parameter keys and values) on one side and a natural-language response (coverage and grounding) on the other.

Figure 3: The same two sub-metrics evaluate a tool call and a natural-language response
For a response turn, the two sub-metrics apply to free text. Completeness asks whether the reply covers the full query, and truthfulness asks whether it’s factually consistent. The same composite applies to an action turn. There, completeness checks the parameter keys, confirming that all required parameters are present. Truthfulness checks the parameter values, confirming they are semantically correct. Both sit on top of a structural check that the right tool and action were selected.
For this post, a turn’s correctness is treated as binary: pass or fail, with a specific failure reason naming the sub-metric and the field. The same decomposition also supports finer-grained grading, scoring individual claims or fields on a continuous scale.
Composed across a dialog, the AEM score is the proportion of turns that pass. Because it’s decomposed by sub-metric, a decline shows which dimension, truthfulness or completeness, drove the change, not just that correctness dropped.
Decomposing and formalizing AEM
Both sub-metrics rely on semantic comparison rather than exact matching. For responses and parameter values, exact string matching is too brittle. “New York City” and “NYC” are semantically equivalent, and “Q3 2024 revenue” and “third quarter revenue figures for 2024” convey the same information.
Semantic similarity scoring determines whether two values are semantically equivalent. Conceptually, the check looks like this:
def evaluate_truthfulness(gold_value, predicted_value, scorer, threshold=0.5):
    """Score semantic equivalence of a predicted value against gold."""
    if gold_value == predicted_value:
        return True, 1.0  # Exact match (fast path)

    score = scorer.score(gold_value, predicted_value)
    return score >= threshold, score
The scorer can be an embedding-based similarity check (fast, cheap) or an LLM-as-judge call (more nuanced). The embedding check is a transparent encoder-plus-similarity-function, and the judge is a more opaque decoder-based model whose scoring isn’t directly inspectable. The threshold controls strictness: a higher threshold catches real errors but risks flagging semantic equivalents, while a lower one is more permissive. The 0.5 here is a neutral default to start from, not a tuned value. The right value depends on your domain’s tolerance for false positives versus false negatives (see Lessons learned).
The similarity score is continuous. The threshold is what collapses it to a binary turn verdict for this post, and a finer-grained setup can retain the per-claim scores instead.
Completeness is checked semantically for response turns (does the response address the full question?) and structurally for action turns (are all required parameter keys present?):
def evaluate_completeness(gold_args, predicted_args):
    """Check all required parameters are present, with no unexpected extras."""
    missing = set(gold_args.keys()) - set(predicted_args.keys())
    extra = set(predicted_args.keys()) - set(gold_args.keys())
    return len(missing) == 0 and len(extra) == 0, missing, extra
The returned missing and extra sets feed directly into the failure taxonomy. A non-empty missing set produces a missing_parameters failure, and a non-empty extra set produces an extra_parameters failure, pinpointing exactly which parameters were wrong.
Composing the score. Decomposition produces per-sub-metric, per-turn verdicts. Composition turns them into one number. The composition rule is itself a choice, in keeping with the framework’s composable principle. The default in this post is an unweighted mean of passing turns.
Other rules are equally valid. Weighted means give more weight to turns that carry higher cost when wrong. Gating rules let a single critical-turn failure cap the score. Per-sub-metric thresholds set a separate bar for each dimension. The framework treats this composition function as pluggable.
Failure taxonomy and action chains
When a turn fails, a specific failure reason captures exactly what went wrong. The taxonomy spans both turn types: response-turn failures sit at the same level as action-turn failures, and the structural checks (tool and action selection) apply only where a turn invokes a tool.
| Failure reason | Applies to | Sub-metric | What it means |
inconsistent_response |
Response turn | Truthfulness | Response not factually consistent with reference |
incomplete_response |
Response turn | Completeness | Response omits part of the requested information |
tool_mismatch |
Action turn | Structural | Wrong tool selected |
action_mismatch |
Action turn | Structural | Right tool, wrong operation |
missing_parameters |
Action turn | Completeness | Required parameter not provided |
extra_parameters |
Action turn | Completeness | Unexpected parameter added |
inconsistent_parameter_values |
Action turn | Truthfulness | Value present but semantically wrong |
prior_action_failed |
Either turn | Cascade | Not a root cause. A prior turn caused this |
The two sub-metrics, truthfulness and completeness, are the constant across both turn types. Only the structural checks are tool-specific. The prior_action_failed label is what makes the metric actionable in a multi-turn setting. It separates root causes from cascading effects, and it can attach to a response turn as readily as to an action turn. The evaluator assigns the label by dependency. A turn is a root cause when its failure originates in that turn. It gets prior_action_failed when it fails only because it consumed an already-failed turn’s output. In the opening example, only turn 2 is a root cause, and turns 3–5 inherit the label. The metric also tracks action chain length (single call, two-step, and complex three-step-plus sequences), since longer chains concentrate most degradation.
Evaluation pipeline for agentic workflows
The metric described earlier runs inside a repeatable pipeline. Annotated dialogs go in, and a single decomposed AEM score comes out, attributed per turn and consumed across the agent lifecycle.
The following diagram shows that end-to-end flow, from annotated dialogs through per-turn scoring and attribution to a single score consumed in development and production.
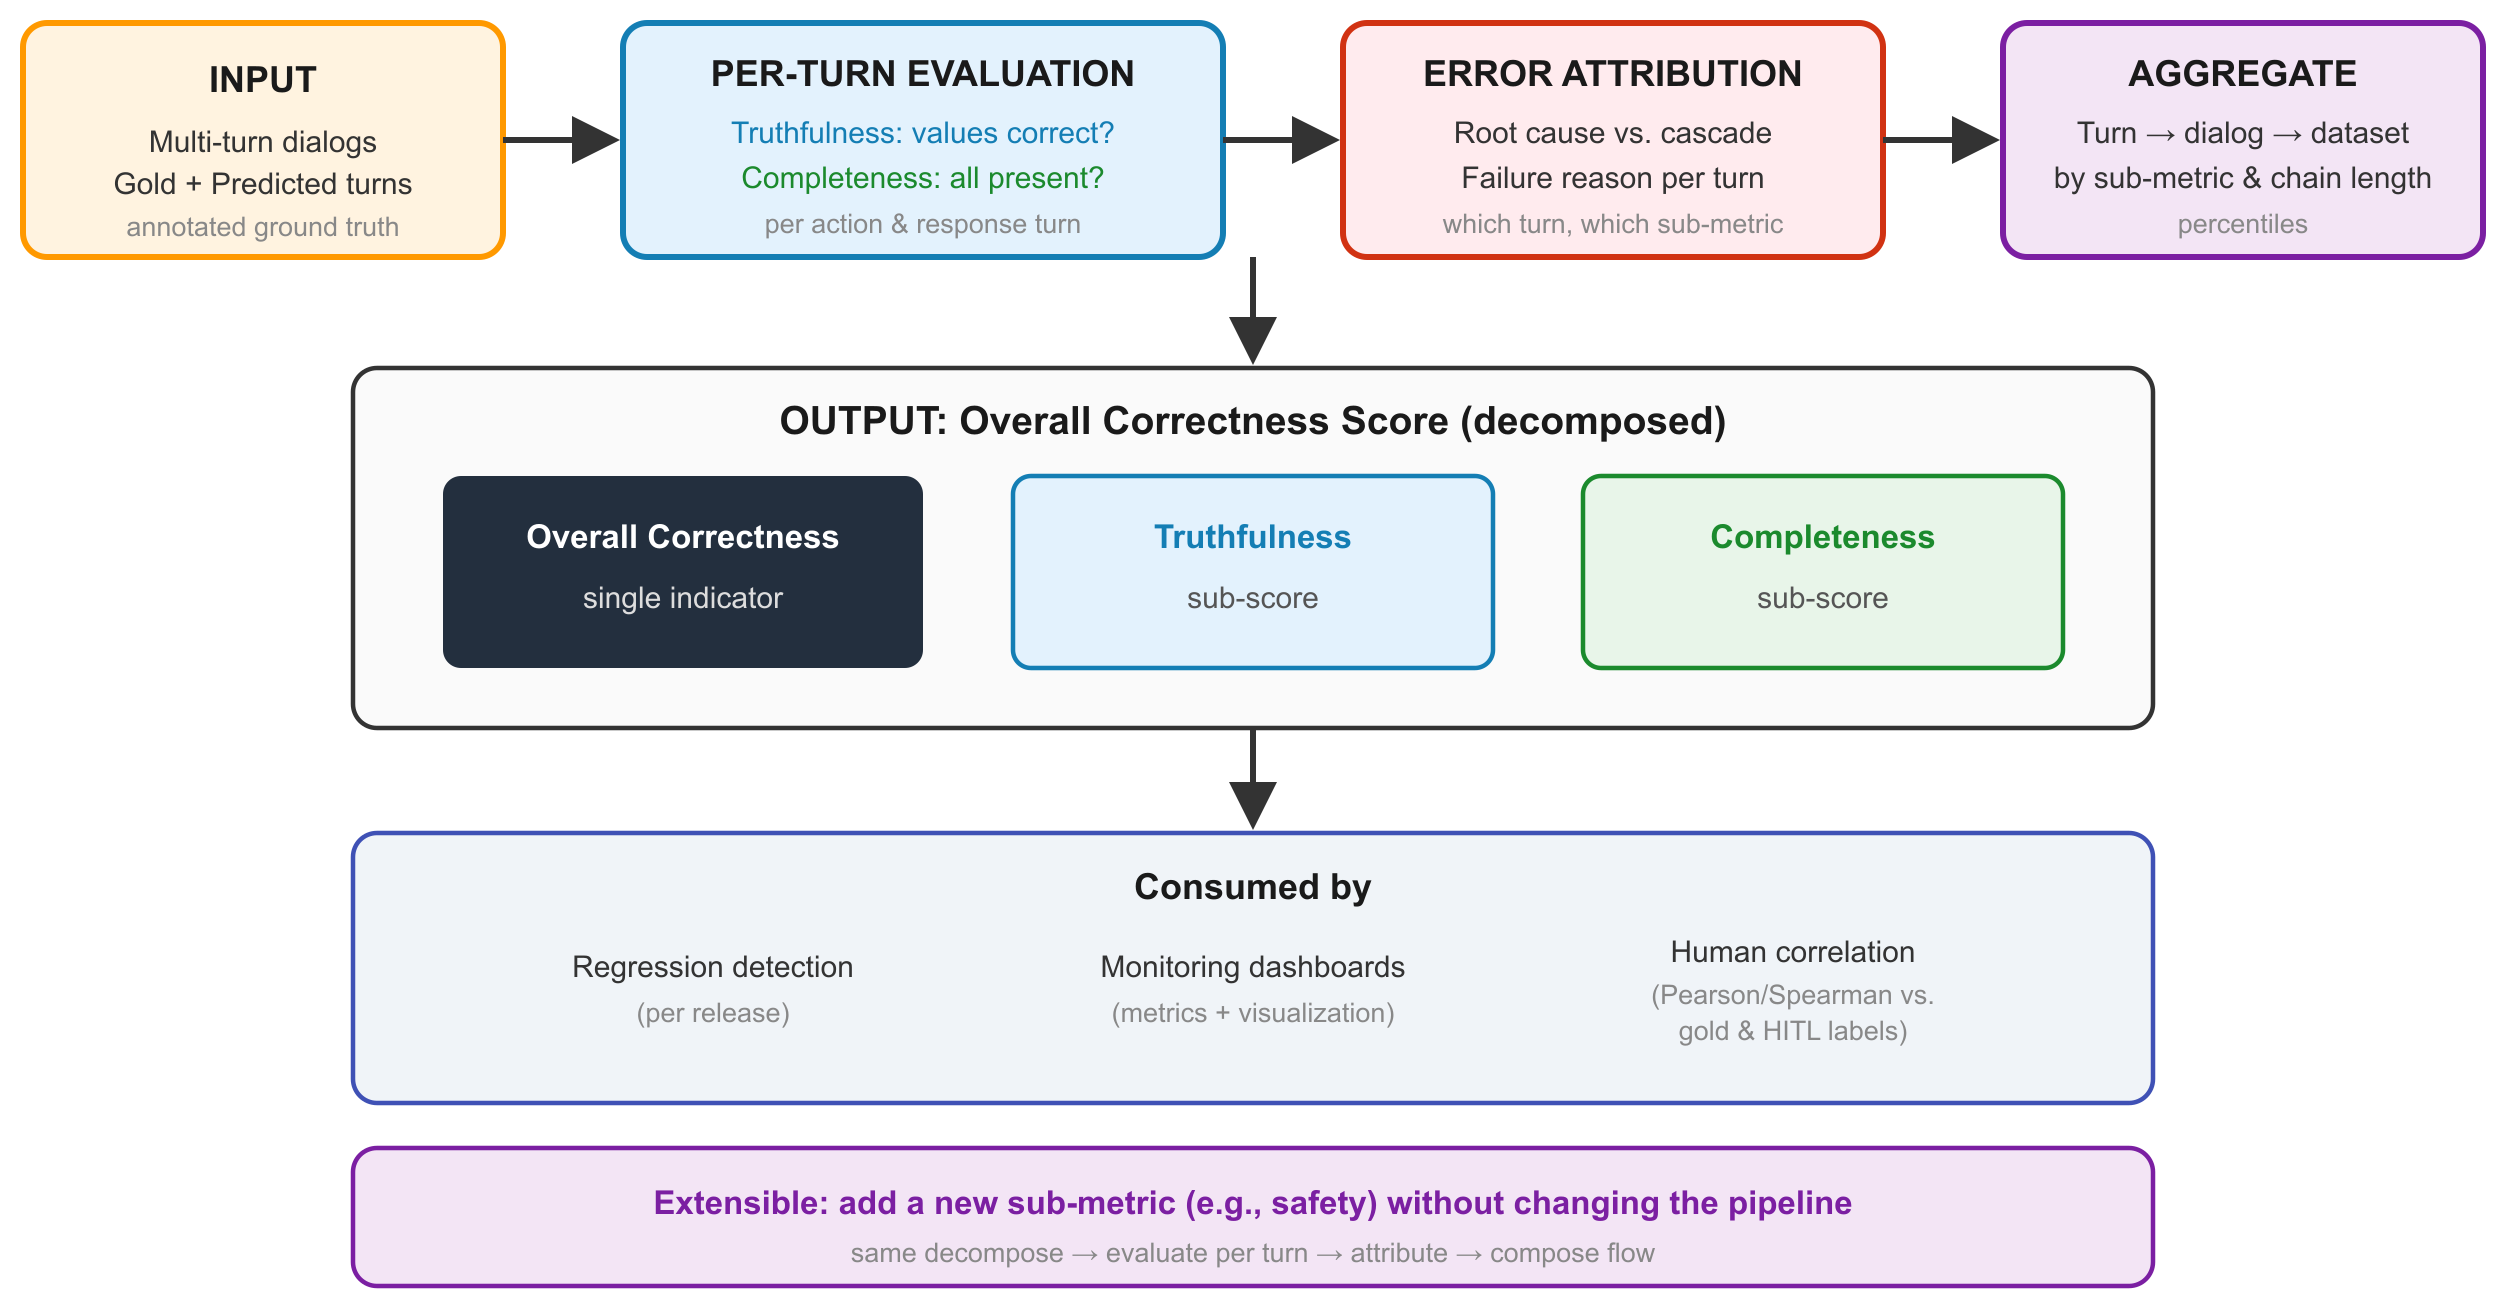
Figure 4: From annotated dialogs to a decomposed, per-turn correctness score
For the five-turn sales-report example, the pipeline returns a compact, decomposed result (illustrative):
{"success_rate": 0.2, "test_pass": false,
 "first_failure_turn": 2, "root_cause": "inconsistent_parameter_values",
 "root_cause_count": 1, "cascading_count": 3}
Golden dataset design
Evaluation begins with ground truth: conversations where both the correct responses and the correct tool calls are annotated. This gold reference is typically human-annotated (or human-reviewed when bootstrapped from a stronger model), since it defines what correct means for each turn. Each dialog is a sequence of turns, and each turn pairs the gold (expected) output with the predicted (actual) output. A turn carries a turn role identifying who produced it. A response turn and an action turn look like this:
[
  {
    "turn_no": 1,
    "turn": "Agent",
    "gold_turn":    {"response": "Which region should the report cover?"},
    "predict_turn": {"response": "Sure, which region would you like the report for?"}
  },
  {
    "turn_no": 2,
    "turn": "Tool",
    "gold_turn":    {"tool_id": "reports", "action": "FilterData",
                     "args": {"metric": "revenue", "region": "EU"}},
    "predict_turn": {"tool_id": "reports", "action": "FilterData",
                     "args": {"metric": "profit",  "region": "EU"}},
    "tags": ["OrderInvariant_filter"]
  }
]
Comparing gold and predicted yields the per-turn correctness verdict. The response turn passes: the wording differs from gold but is semantically equivalent, which is exactly what semantic similarity scoring is for. The action turn fails: a truthfulness error surfaces on the metric value (profit where revenue was expected). The tags field supports order-invariant evaluation. When multiple tool calls are valid in any order, such as checking a calendar and searching flights, the evaluator checks against valid orderings. It does not penalize correct but differently sequenced behavior.
Error attribution
After every turn is evaluated, error attribution separates root causes from cascading effects. It operates on turn verdicts regardless of whether a turn was a response or an action:
def attribute_errors(turn_results):
    """Separate root cause failures from cascading failures."""
    root_causes = []
    cascading = []

    for result in turn_results:
        if not result.success:
            if result.failure_reason == "prior_action_failed":
                cascading.append(result)
            else:
                root_causes.append(result)

    return {
        "first_failure_turn": root_causes[0].turn_no if root_causes else None,
        "root_cause": root_causes[0].failure_reason if root_causes else None,
        "total_failures": len(root_causes) + len(cascading),
        "root_cause_count": len(root_causes),
        "cascading_count": len(cascading),
    }

# Example output:
# first_failure_turn: 2, root_cause: "inconsistent_parameter_values"
# root_cause_count: 1, cascading_count: 3
# Fix the parameter in turn 2; turns 3-5 likely resolve automatically.
This changes how teams prioritize fixes. Instead of investigating every failure independently, they focus on root causes, since cascading failures often resolve after the root is fixed. A single root cause in a multi-step chain can otherwise appear as several distinct failures.
Production monitoring
In production, the overall correctness score is tracked continuously:
- Overall correctness by release (regression detection): Did the late